[翻译]在 Claude Code 中选择 Claude 模型和努力级别
原文信息
- 作者: Lydia Hallie
- 日期: 2026年7月7日
- 阅读时间: 5 分钟
- 分类: Claude Code, Enterprise AI
- 产品: Claude Code
- 原文链接: Choosing a Claude Model and Effort Level in Claude Code
Key Takeaways 关键要点
Model selection chooses the set of fixed weights, or the overall capability range of the model. While models can be provided context or steered, the model’s overall knowledge base and capabilities are set.
模型选择决定了固定权重的集合,即模型的总体能力范围。虽然可以为模型提供上下文或引导,但模型的总体知识库和能力是固定的。
Effort means more than “thinking time.” It controls how much work Claude does on your request overall including the number of files read, tools used, and how many steps it takes before it checks back in with you.
努力不仅仅意味着”思考时间”。它控制 Claude 在你的请求上总体做多少工作,包括读取多少文件、使用多少工具,以及在向你确认之前采取多少步骤。
Choose smaller models for more routine tasks and larger models for more complex or ambiguous tasks. Start with default effort levels for each model and tune as a general preference based on the type of work you do rather than task-by-task.
对于常规任务选择更小的模型,对于更复杂或模糊的任务选择更大的模型。从每个模型的默认努力级别开始,根据你做的工作类型作为通用偏好来调整,而不是逐个任务决定。
If Claude has all the pertinent context, clearly tried, and still got it wrong, that’s a signal to pick a more capable model. If Claude got it wrong by skipping a file, not running the tests, or bailing on a refactor partway through, pick a higher effort level.
如果 Claude 拥有了所有相关上下文且明显尝试过但仍然出错,这是选择更有能力模型的信号。如果 Claude 因为跳过文件、没有运行测试或在重构中途放弃而出错,选择更高的努力级别。
Claude Code Effort Level and Model Selection Claude Code 努力级别和模型选择
Claude Code gives you two settings that appear to “make the answer better”: the model setting and the effort level. You may expect that larger models like Claude Fable 5 provide a smarter output than Claude Sonnet, and a higher effort level means Claude thinks longer before it answers.
Claude Code 给你两个看起来”让答案更好”的设置:模型设置和努力级别。你可能期望像 Claude Fable 5 这样更大的模型比 Claude Sonnet 提供更聪明的输出,而更高的努力级别意味着 Claude 在回答前思考更长时间。
The first assumption is accurate. Our largest models are more capable, according to industry-standard benchmarks.
第一个假设是准确的。根据行业标准基准,我们最大的模型更有能力。
But effort means more than just “thinking time.” Effort level controls how much work Claude does on your request overall. This does include how long the model thinks, but also:
但努力不仅仅意味着”思考时间”。努力级别控制 Claude 在你的请求上总体做多少工作。这确实包括模型思考多长时间,但也包括:
How many files it reads;
读取多少文件;
How much it verifies; and
验证多少;以及
How far it pushes through a multi-step task before checking in with you.
在向你确认之前能推进多步骤任务多远。
At a higher effort, Claude will take more of those actions (for example, read files, run tests, and double-check) before it comes back to you. At lower effort, it would rather ask you for more context than spend tokens figuring something out on its own.
在更高的努力级别下,Claude 会在返回之前采取更多这些操作(例如,读取文件、运行测试和双重检查)。在更低的努力级别下,它宁愿请求你提供更多上下文,而不是花费 token 自己弄清楚。
How Model Selection Works 模型选择如何工作
When you press enter, Claude Code assembles your message together with the system prompt, tool definitions, your CLAUDE.md, the conversation history, and any files in context. All of this is sent as one request to the API.
当你按 Enter 时,Claude Code 将你的消息与系统提示、工具定义、你的 CLAUDE.md、对话历史以及上下文中的任何文件组装在一起。所有这些都作为一次请求发送到 API。
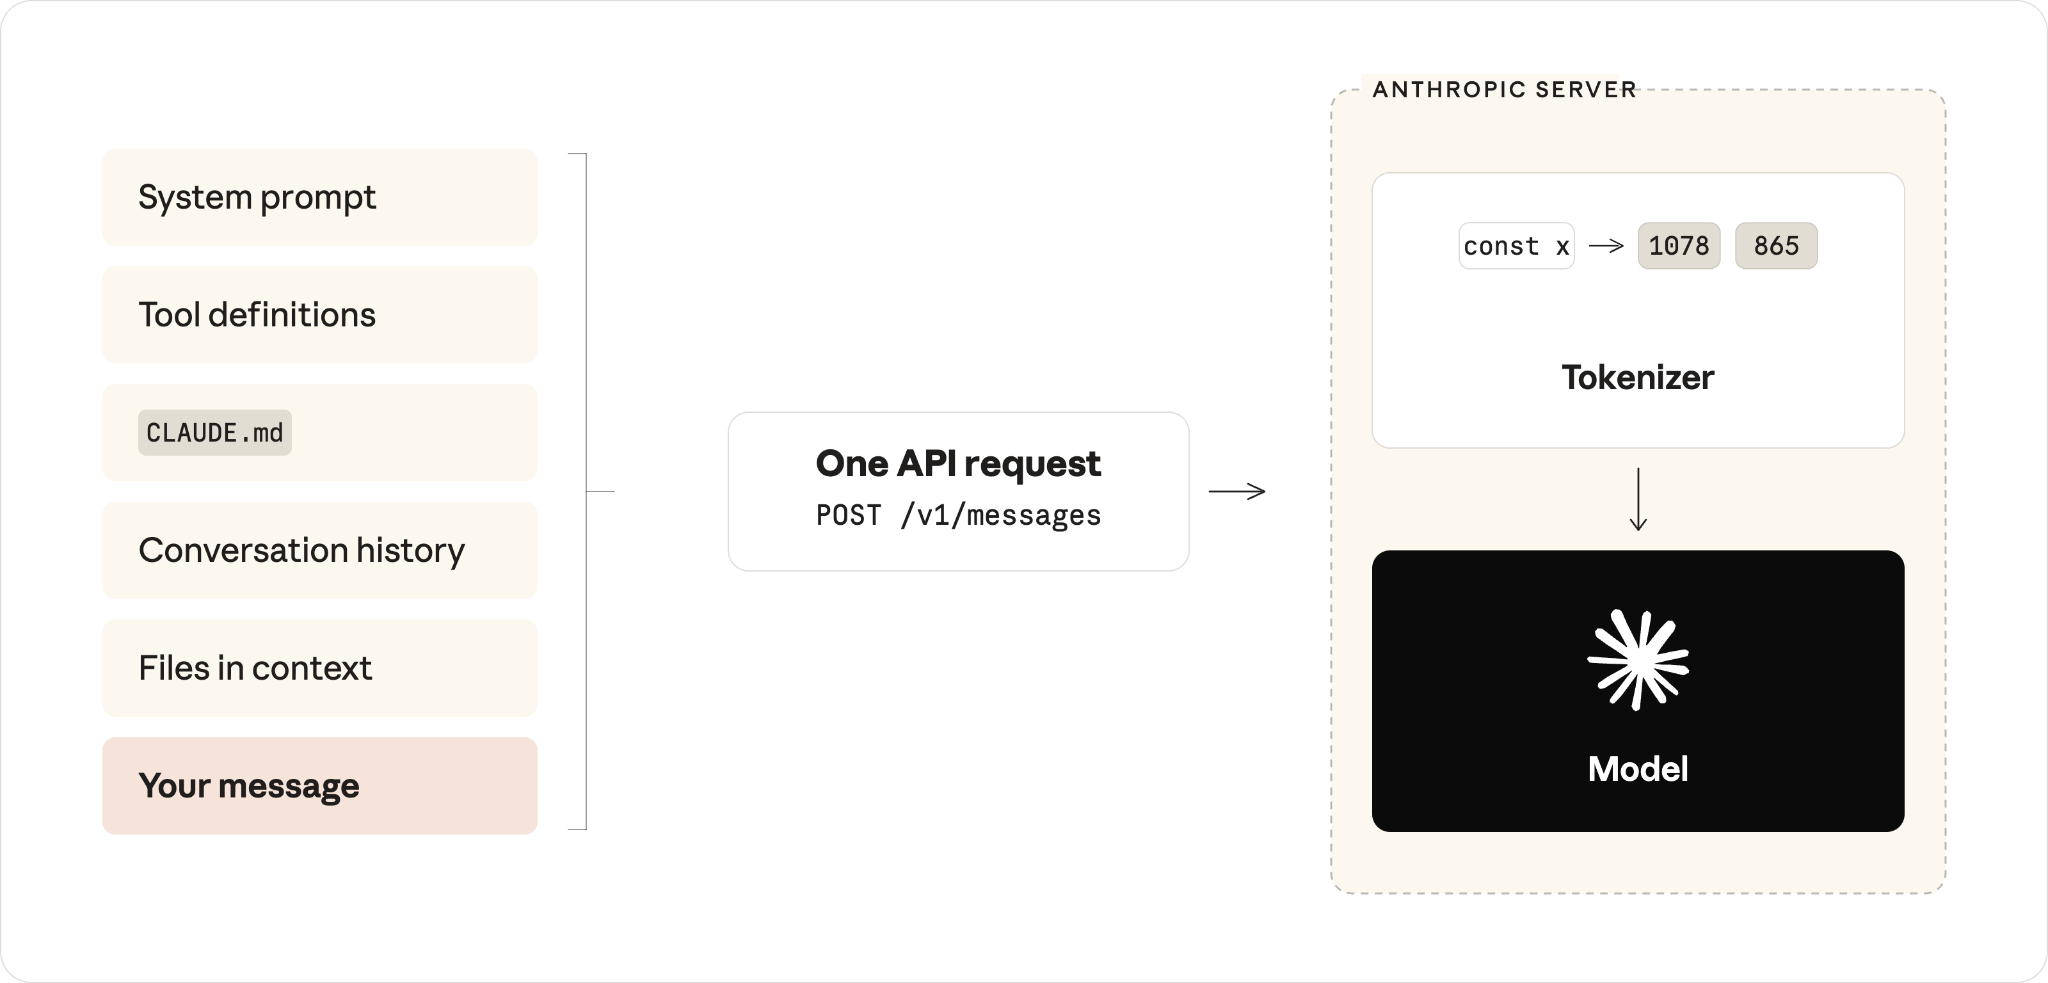
Everything Claude Code has gets packed into one API request.
Claude Code 拥有的所有东西都被打包成一次 API 请求。
On the server, the text is tokenized before it ever reaches the model. The model never sees that as plain text, though. The first thing that happens on the server is tokenization: the text is split into pieces, and each piece is mapped to an integer from a fixed vocabulary the model was trained with. const might map to 1978, await might map to 4293.
在服务器上,文本在到达模型之前就被分词了。模型永远不会看到纯文本。服务器上发生的第一件事是分词:文本被分割成片段,每个片段被映射到模型训练时使用的固定词汇表中的一个整数。const 可能映射到 1978,await 可能映射到 4293。
From here on, your prompt is an array of integers.
从现在开始,你的提示是一串整数数组。
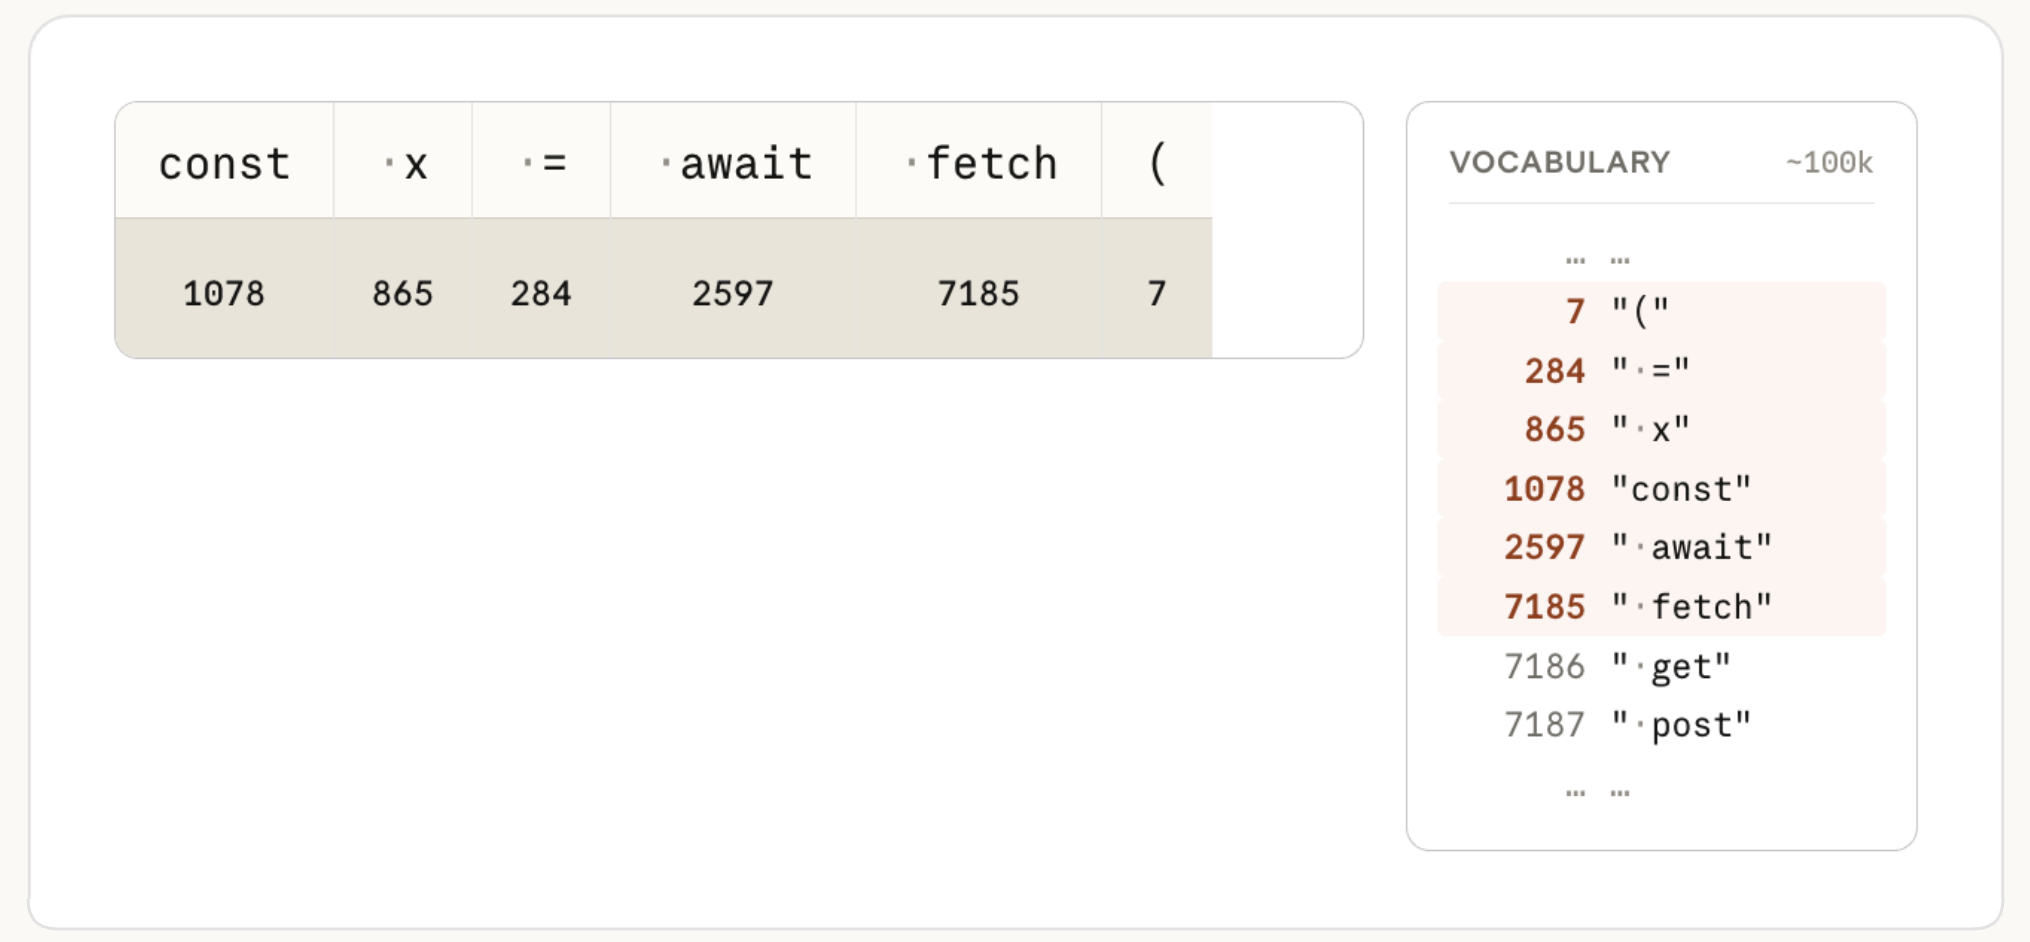
The tokenizer splits your text into pieces and maps each piece to an integer in a fixed vocabulary. Each chunk in the top row becomes its token ID (bottom row); IDs shown are illustrative.
分词器将你的文本分割成片段,并将每个片段映射到固定词汇表中的一个整数。顶行的每个块变成其 token ID(底行);显示的 ID 是说明性的。
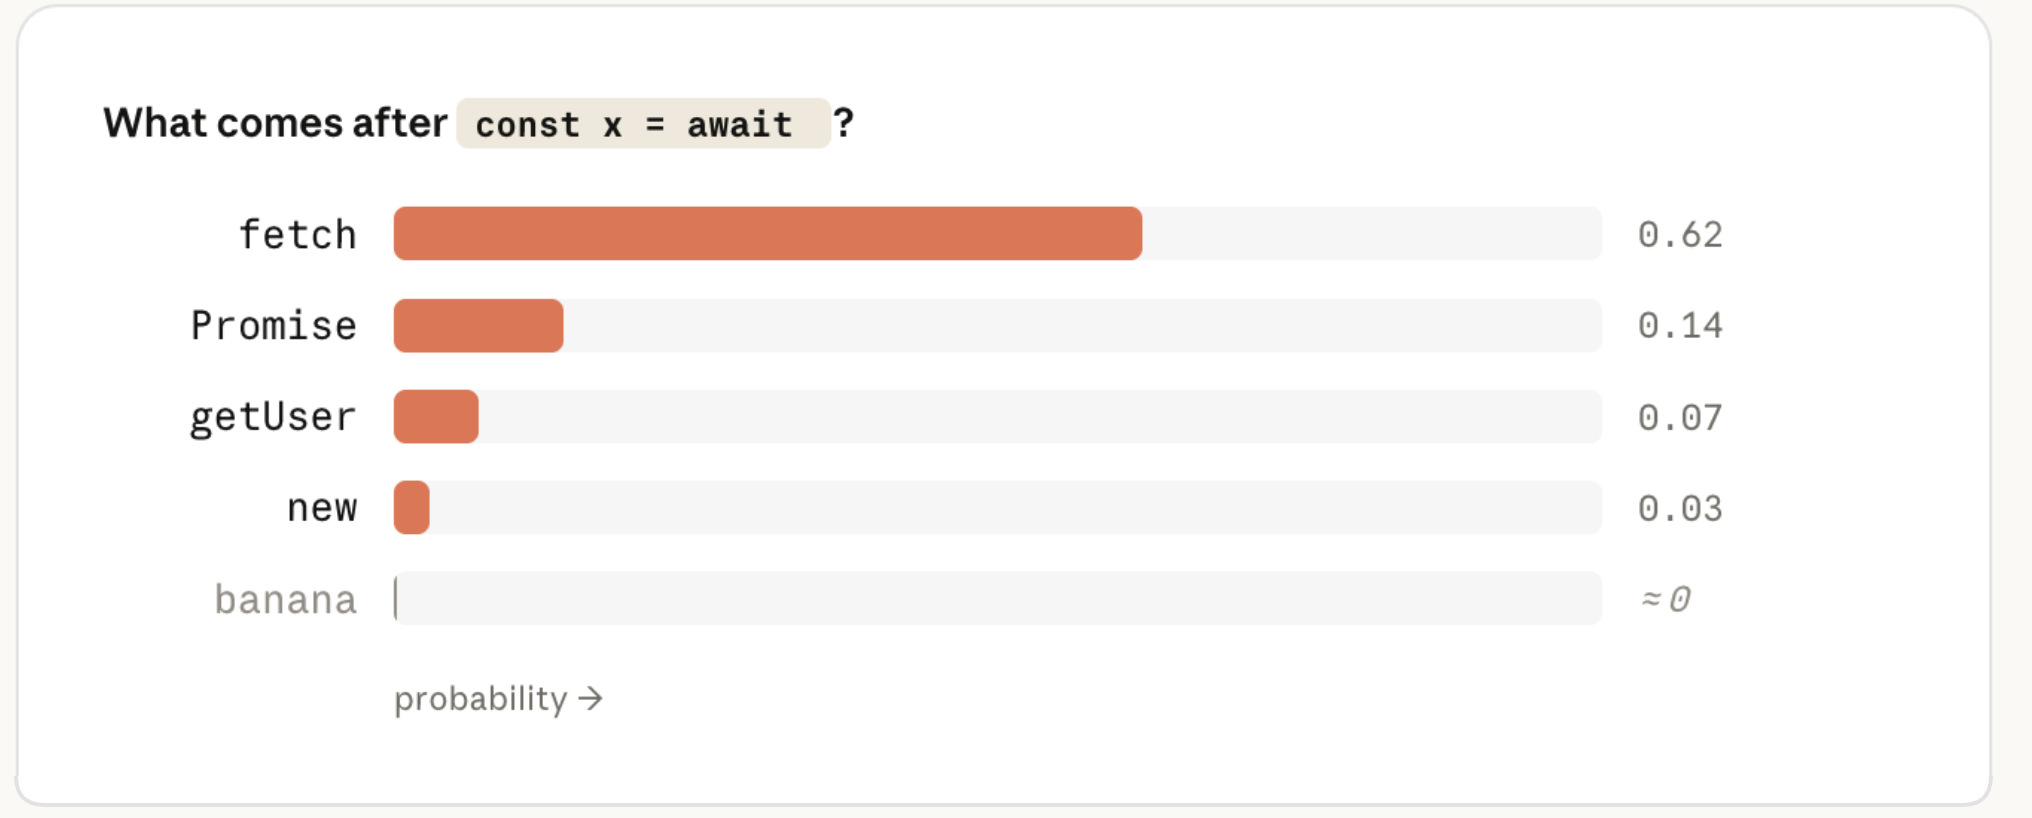
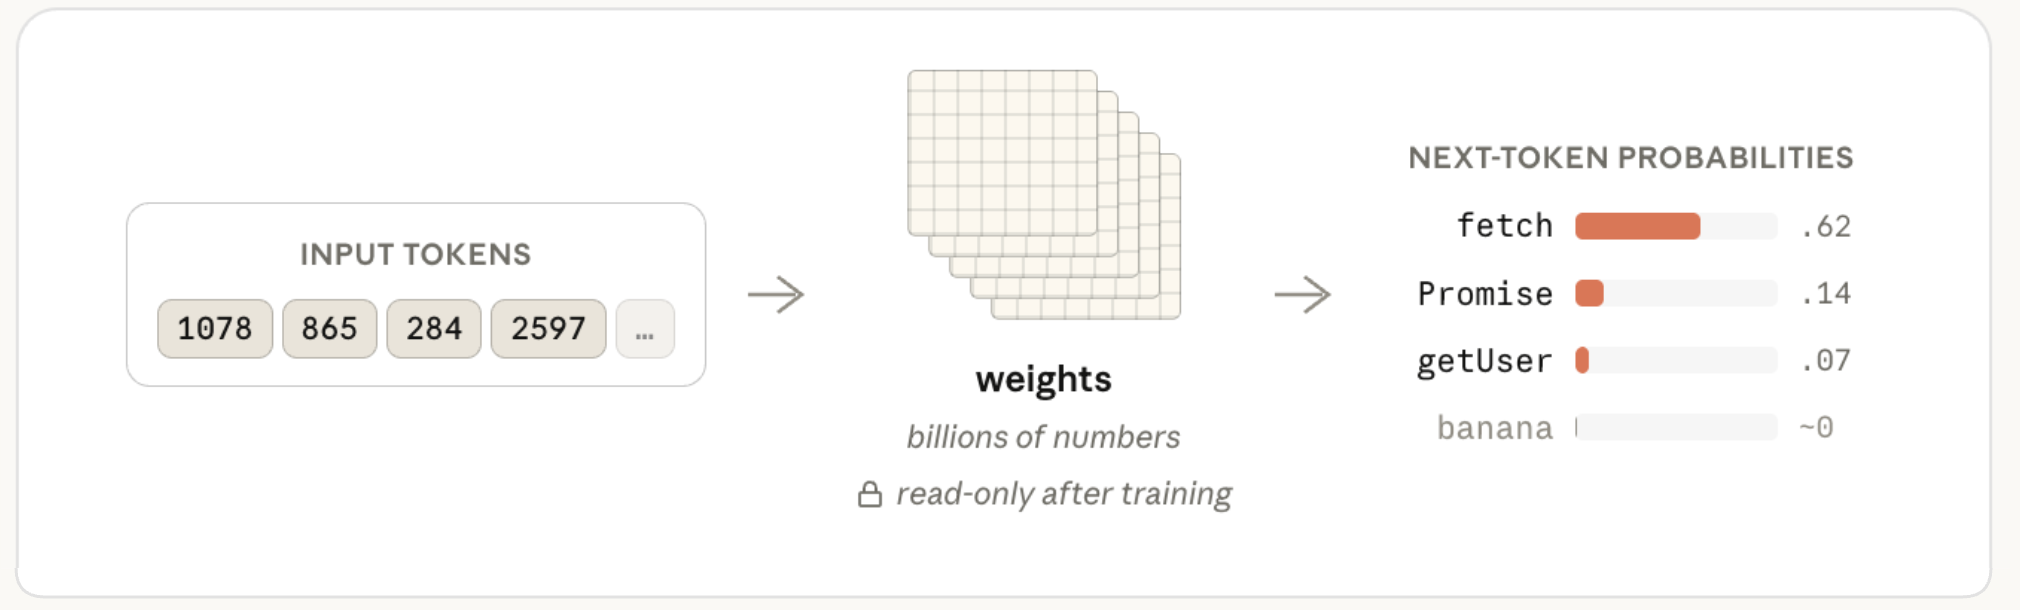
The model’s job is to take that array and predict which token comes next. It does this by computing a probability for every token in its vocabulary and picking from the top.
模型的工作是获取该数组并预测下一个 token 是什么。它通过计算其词汇表中每个 token 的概率并从最高概率中选择来做到这一点。
After const x = await, a well-trained model puts high probability on fetch (very likely) and near-zero on banana (not likely at all).
在 const x = await 之后,训练良好的模型会对 fetch 给予高概率(非常可能)而对 banana 给予接近零的概率(完全不可能)。
The model’s prediction is a probability for every token in its vocabulary. The gap between the top guess and an unrelated one is enormous.
模型的预测是其词汇表中每个 token 的概率。最高猜测与无关猜测之间的差距是巨大的。
What turns your input tokens into those probabilities is the weights (also called parameters). These are billions of numbers organized into large matrices.
将输入 token 转化为这些概率的是权重(也称为参数)。这些是数十亿个数字,组织成大型矩阵。
To predict one token, the model runs your input through those matrices, a long chain of matrix multiplications, and reads the probabilities at the end.
为了预测一个 token,模型通过这些矩阵运行你的输入,一长串矩阵乘法,然后在末尾读取概率。
The weights are where everything the model “knows” lives.
权重是模型”知道”的所有东西的所在。
The weights of each model are set during training, and by the time you’re sending requests they’re read-only. Nothing in your prompt, your CLAUDE.md, or your context changes them.
每个模型的权重在训练期间设置,当你发送请求时它们已是只读的。你的提示、你的 CLAUDE.md 或你的上下文中的任何内容都不会改变它们。
(If you’ve run into the word inference, that’s all it means: using the model after training is done, with the weights fixed.)
(如果你遇到过”推理”这个词,这就是它的全部含义:在训练完成后使用模型,权重是固定的。)
Your prompt goes in, probabilities come out. The weights in the middle don’t change.
你的提示进去,概率出来。中间的权重不变。
Everything Claude knows about TypeScript, popular frameworks, idiomatic Go, or any other general programming knowledge, was encoded into those weights at training time.
Claude 关于 TypeScript、流行框架、地道的 Go 或任何其他一般编程知识的一切都是在训练时编码到这些权重中的。
Your prompt and context can still steer the prediction (putting your real code in front of Claude is steering, and it works really well), but they don’t add anything to the weights themselves.
你的提示和上下文仍然可以引导预测(把你的真实代码放在 Claude 面前是引导,而且效果很好),但它们不会给权重本身增加任何东西。
If a library didn’t exist when the model was trained, it isn’t in the weights. You can put the docs in context and Claude will use them, but that’s steering, not teaching. Claude’s response will only be influenced for that request; the underlying model hasn’t retained the information.
如果一个库在模型训练时不存在,它就不会在权重中。你可以把文档放在上下文中,Claude 会使用它们,但那是引导,不是教学。Claude 的响应只会对该请求产生影响;底层模型并没有保留这些信息。
So when Claude confidently calls an API that doesn’t exist (a hallucination), that’s the weights producing a token sequence that looks plausible from training patterns, not a failed lookup.
所以当 Claude 自信地调用一个不存在的 API 时(幻觉),那是权重产生的一个从训练模式看起来合理的 token 序列,而不是失败的查找。
So what does changing the model actually do? It swaps which set of frozen weights handles your request.
那么改变模型实际上做什么?它切换哪组冻结权重来处理你的请求。
The model doesn’t generate a whole answer at once. It predicts one token, appends it to the sequence, and runs the whole computation again to get the next one. A 200-token response is 200 separate passes through the weights. This loop is where most of your wait time and your output cost come from.
模型不会一次生成整个答案。它预测一个 token,将其追加到序列中,然后再次运行整个计算以获得下一个。200 个 token 的响应是 200 次单独的权重传递。这个循环是你大部分等待时间和输出成本的原因。
The sequence grows by exactly one token per step. The model re-reads the whole array each time to predict what comes next.
序列每步恰好增长一个 token。模型每次都重新读取整个数组来预测下一个是什么。
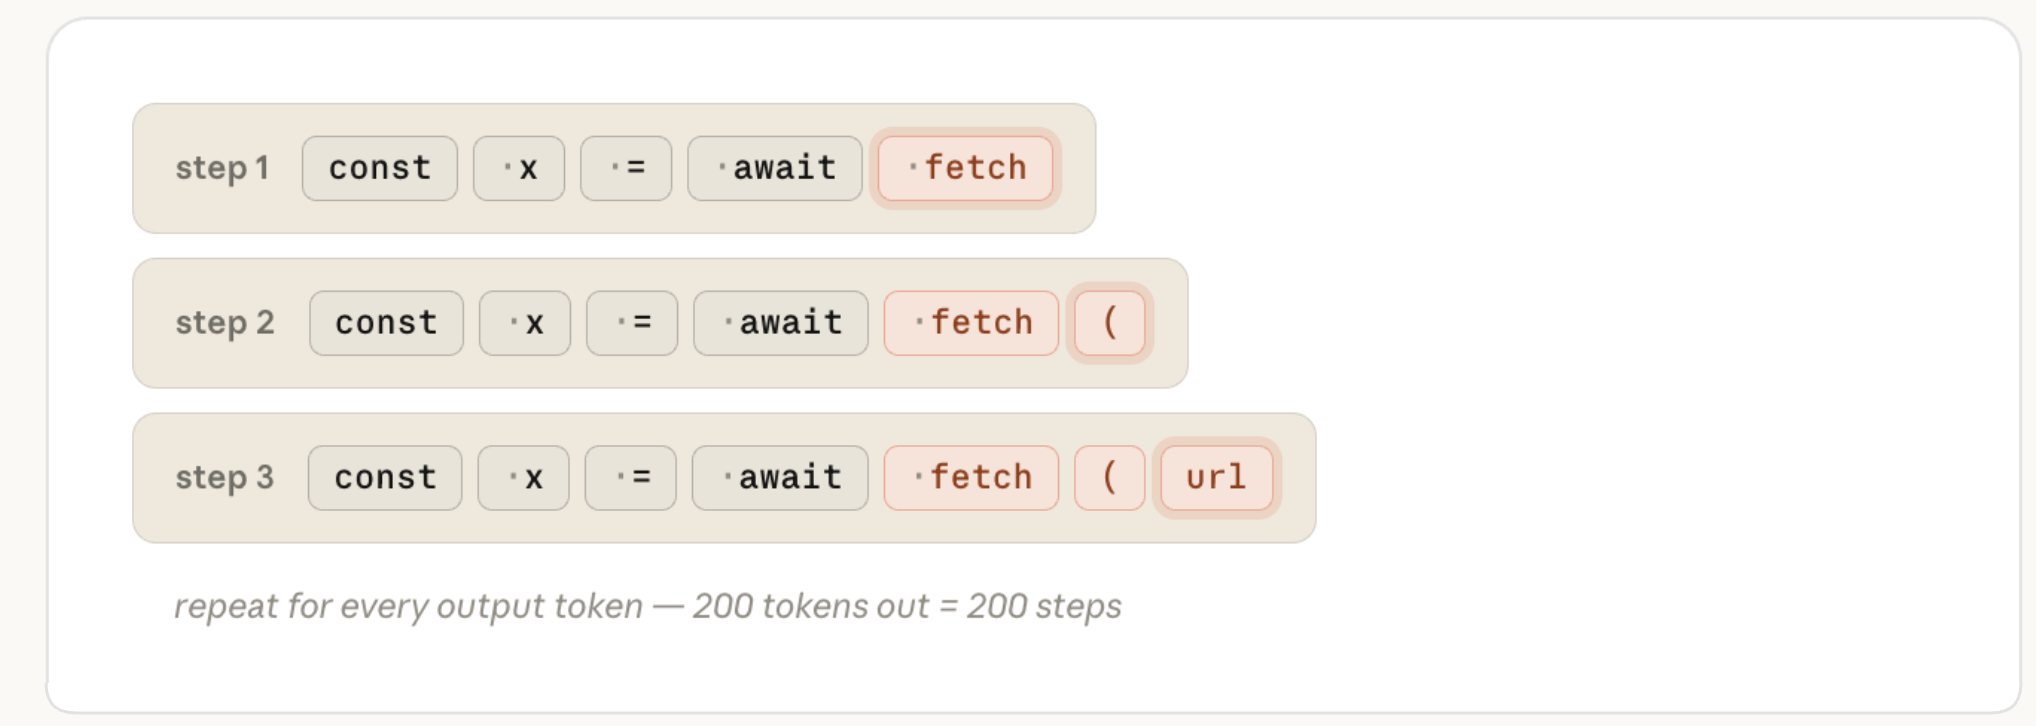
So the model setting decides which weights handle your request, and it also decides what each output token costs.
所以模型设置决定哪些权重处理你的请求,也决定每个输出 token 的成本。
What it doesn’t decide is how many tokens get generated. That number can vary a lot for the same prompt, depending on how much work Claude decides to do.
它不决定生成多少 token。这个数字对于相同的提示可能会有很大差异,取决于 Claude 决定做多少工作。
This is what effort level controls: how much work Claude decides to do for each turn.
这正是努力级别控制的:Claude 决定在每个回合做多少工作。
How Claude Code Effort Level Works Claude Code 努力级别如何工作
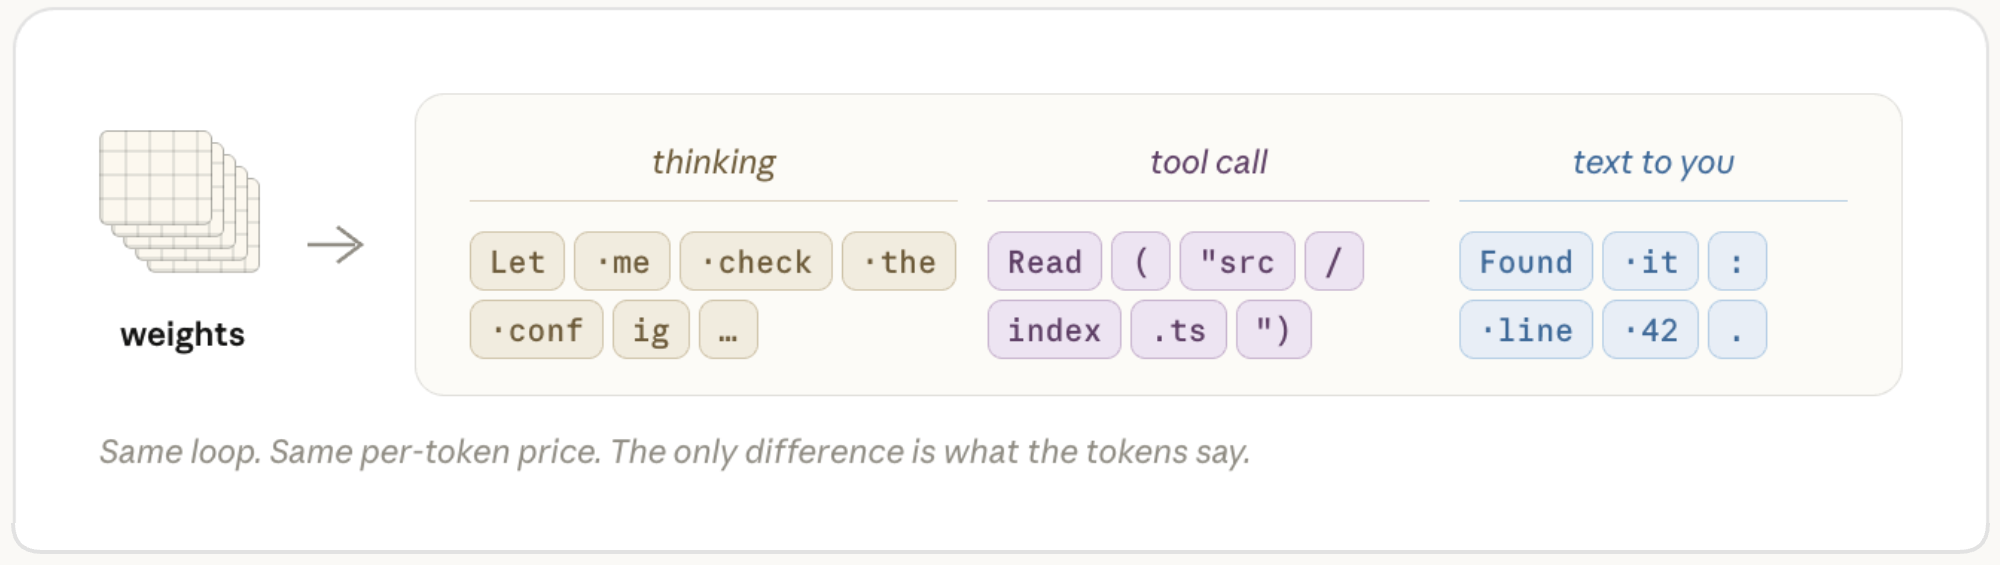
When Claude Code is working on a task, the tokens it generates fall into a few categories:
当 Claude Code 处理任务时,它生成的 token 分为几类:
Thinking: the reasoning you see streaming before and between actions.
思考:你看到在操作之前和之间流式输出的推理。
Tool calls: structured blocks naming a tool like Read or Edit and its arguments, which Claude Code then parses and executes.
工具调用:命名工具(如 Read 或 Edit)及其参数的结构化块,然后 Claude Code 解析并执行它们。
Text to you: the plan, progress updates, the summary at the end.
给你的文本:计划、进度更新和最后的总结。
These are all ordinary output tokens from the same loop, billed at the same rate. For example, thinking tokens are generated exactly like the other output tokens and stay in context for the rest of that turn.
这些都是同一循环中的普通输出 token,按相同费率计费。例如,思考 token 与其他输出 token 的生成方式完全相同,并在该回合的剩余时间内保留在上下文中。
When Claude moves on to writing code, its earlier reasoning is part of the input just like a file it’s read.
当 Claude 继续编写代码时,它之前的推理作为输入的一部分,就像它读取的文件一样。
All of Claude’s output is tokens. Thinking, tool calls, and text to you are all generated from the same loop.
Claude 的所有输出都是 token。思考、工具调用和给你的文本都是从同一个循环生成的。
How does effort change any of this? The effort level is sent to the model as part of the request, right alongside your prompt. The model was trained to understand how to behave at each effort level and that learned behavior is baked into the frozen weights.
努力如何改变这些?努力级别作为请求的一部分与你的提示一起发送给模型。模型被训练来理解在每个努力级别下如何行为,那种学习到的行为被烘焙到冻结权重中。
When your request arrives, effort level is one more input the model responds to, the same way it responds to your prompt text. This sets Claude’s behavior for how thorough and certain it needs to be before it considers the task done.
当你的请求到达时,努力级别是模型响应的另一个输入,就像它响应你的提示文本一样。这设定了 Claude 的行为:它需要多么彻底和确定才能认为任务完成。
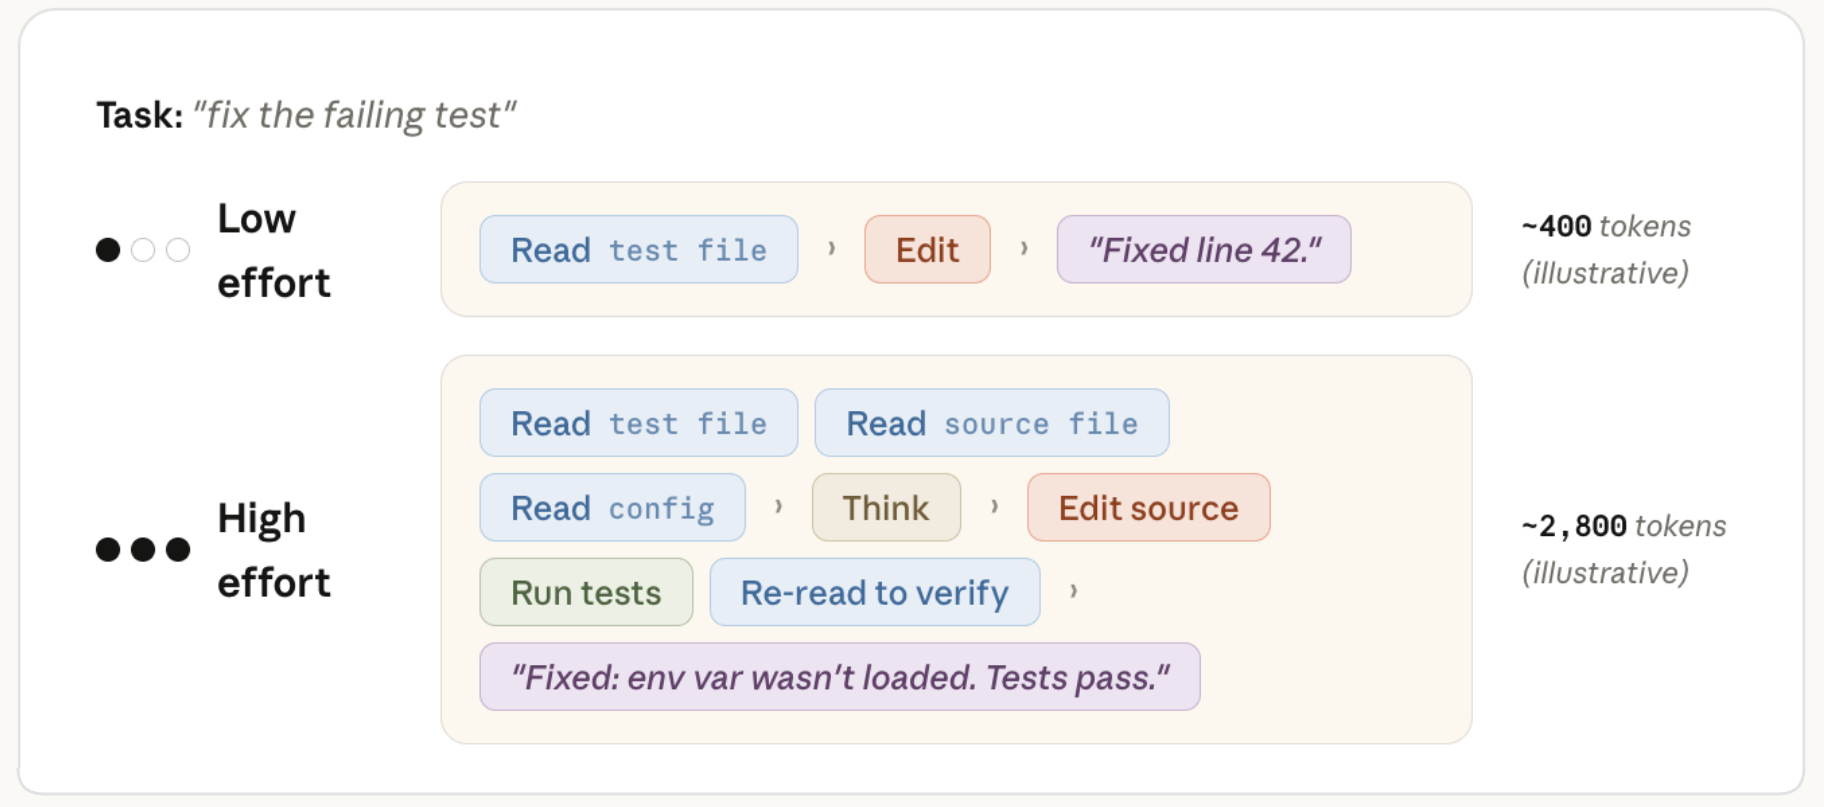
This is considered on every turn and results in more tokens to produce higher confidence answers.
每个回合都会考虑这一点,并生成更多 token 以产生更高置信度的答案。
Same prompt, two effort levels. The high effort path generates roughly 7x more tokens to reach a higher confidence answer.
相同的提示,两个努力级别。高努力路径生成大约 7 倍的 token 以达到更高置信度的答案。
At higher effort levels, Claude often starts with creating a plan and the level of effort influences the depth and breadth of that plan. However, the plan is not frozen in place. As Claude receives results from its actions, it updates the progress that has been made and how certain it is of the accumulated result.
在更高的努力级别下,Claude 通常从创建计划开始,努力级别影响该计划的深度和广度。然而,计划不是一成不变的。当 Claude 收到其操作的结果时,它会更新已取得的进展以及它对累积结果的确定程度。
So when step 1 of a three-hypothesis debugging plan finds the bug, “investigate hypotheses 2 and 3” may no longer be necessary actions. Claude will typically say this explicitly, “the first check found it, so the remaining checks aren’t needed” and skip ahead. You see this happen in Claude Code when task lists get revised mid-run.
所以当三假设调试计划的第一步找到 bug 时,”调查假设 2 和 3”可能不再是需要操作。Claude 通常会明确说明这一点,”第一次检查找到了,所以剩余的检查不需要”然后跳过。你会在 Claude Code 中看到这种情况发生,当任务列表在运行中途被修改时。
Claude will be more predisposed to double-checking additional hypotheses or verifying correctness at higher effort levels, but it generally won’t artificially inflate usage for simple tasks at higher effort levels. In fact, our team pays close attention to “overthinking” during model training as it degrades effectiveness.
在更高的努力级别下,Claude 更倾向于双重检查其他假设或验证正确性,但通常不会在更高努力级别下对简单任务人为增加用量。事实上,我们的团队在模型训练期间非常关注”过度思考”,因为它会降低效率。
Picking an Effort Level 选择努力级别
Our guidance is that for most tasks you should use the model’s default effort level. The default is the level where Claude will scale its token usage according to what most people would want to spend on a task.
我们的指导是,对于大多数任务,你应该使用模型的默认努力级别。默认级别是 Claude 根据大多数人在任务上愿意花费的来调整 token 使用量的级别。
Think of effort as a manual override to scale how hard and long Claude works. Choose it deliberately when you have a strong preference for thoroughness or speed based on your domain or the type of work you do. Consider this more as a general preference than a task-by-task decision.
把努力想象成一个手动覆盖,用来调整 Claude 工作的难度和时长。当你对彻底性或速度有强烈偏好时,有意识地选择它,根据你的领域或你做的工作类型。把这更多地看作一种通用偏好,而不是逐个任务的决定。
Some practical insight that may help guide you following the launch of Claude Opus 4.8: in our testing we found when you use the default effort setting for Opus 4.8, it will produce better results for about the same number of tokens when compared to using the default effort setting of Opus 4.7 for the same task.
一些在 Claude Opus 4.8 发布后可能帮助指导你的实践见解:我们的测试发现,当你使用 Opus 4.8 的默认努力设置时,与对同一任务使用 Opus 4.7 的默认努力设置相比,它会产生更好的结果,而 token 数量大致相同。
What to Change When Claude Gets It Wrong 当 Claude 出错时改变什么
When Claude gets something wrong, your first instinct shouldn’t be to adjust a knob, but to examine the context you have provided. Is your prompt too vague? Is Claude connected to the right tools? Equipped with the right skills?
当 Claude 出错时,你的第一个本能不应该是调整旋钮,而是检查你提供的上下文。你的提示太模糊了吗?Claude 连接了正确的工具吗?配备了正确的技能吗?
If you’re increasing effort on a task that shouldn’t need it, the fix is often upstream, in your context, your CLAUDE.md, or how the task is scoped.
如果你在一个不应该需要它的任务上增加努力,修复通常在上游,在你的上下文、你的 CLAUDE.md 中,或者在任务的范围划分方式中。
But assuming you have provided clear context and Claude still gets something wrong, the question to ask yourself is: did it not try hard enough, or did it not know enough?
但假设你已经提供了清晰的上下文但 Claude 仍然出错,问自己这个问题:它是不够努力,还是不够了解?
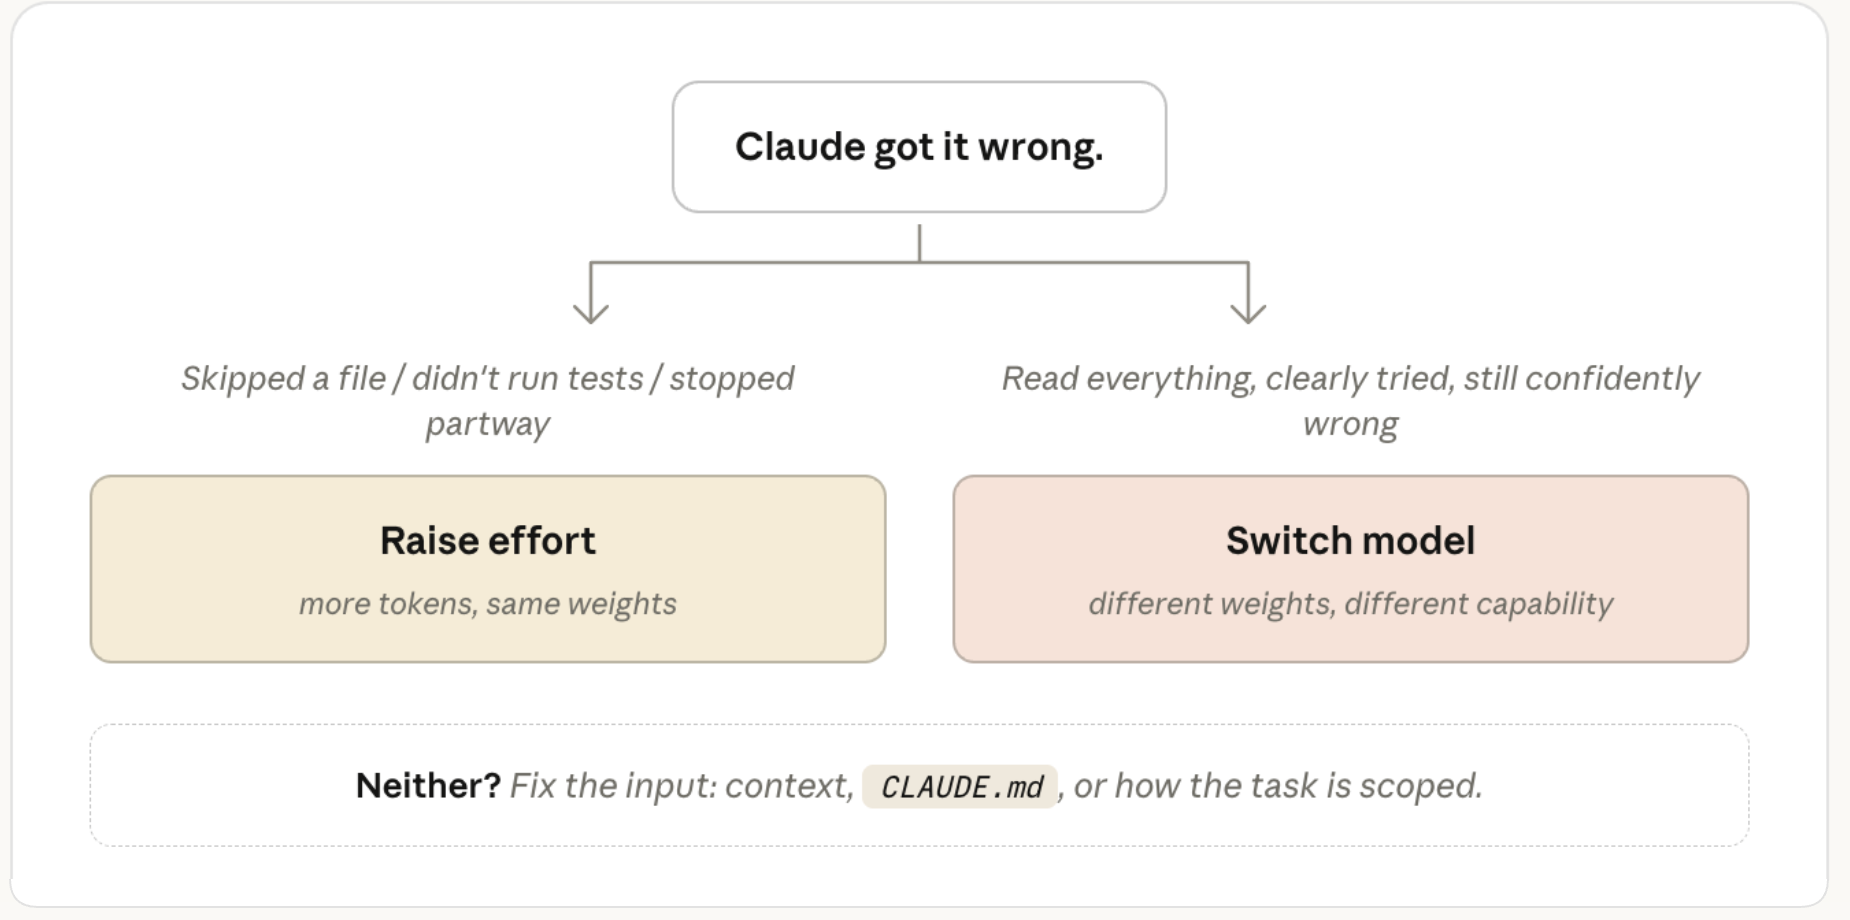
Two questions, one fallback. Use the heuristic to pick a starting point, not a hard rule.
两个问题,一个后备。使用这个启发式方法选择起点,而不是硬性规则。
Model: The Problem Was Too Hard 模型:问题太难了
Pick a larger model when the problem is genuinely hard. For example, problems like subtle bugs, unfamiliar domains, or architecture decisions. A larger model is helpful for situations where the smaller model is confidently wrong no matter how much context you give it.
当问题确实困难时选择更大的模型。例如,微妙的 bug、不熟悉的领域或架构决策等问题。更大的模型对于较小模型无论你给多少上下文都自信地出错的情况很有帮助。
Larger models are also better at handling ambiguity, whereas specific instructions directing execution are a better recipe for success on the smaller models.
更大的模型也更好地处理歧义,而引导执行的具体指令是较小模型成功的更好方法。
Pick a smaller model when the work is routine. For example, edits you can describe precisely, mechanical changes, or questions about code that’s already in context. There’s no reason to pay for capability the task doesn’t need.
当工作是常规的时候选择更小的模型。例如,你可以精确描述的编辑、机械性的更改,或关于上下文中已有代码的问题。没有理由为任务不需要的能力付费。
If Claude has all the pertinent context and clearly tried and still got it wrong, that’s a signal to pick a larger model.
如果 Claude 拥有了所有相关上下文且明显尝试过但仍然出错,这是选择更大模型的信号。
If you’re on the larger model and the work has been routine for a while, dropping down will increase speed and typically reduce cost without impacting the quality of the output.
如果你在更大的模型上且工作已经常规一段时间了,降下来会提高速度,通常降低成本而不影响输出质量。
Effort: Claude Didn’t Try Hard Enough 努力:Claude 不够努力
Pick a higher effort level if Claude got it wrong by skipping a file, not running the tests, or not double-checking its work. This is most relevant if you selected an effort level below the model’s default.
如果 Claude 因为跳过文件、没有运行测试或没有双重检查工作而出错,选择更高的努力级别。如果你在模型的默认设置之下选择了努力级别,这最相关。
Fable vs. Opus vs. Sonnet: The Specialist, the Expert, and the Generalist Fable vs. Opus vs. Sonnet:专家、通才和通才
One way I like to think about how the two settings relate: Fable is a specialist who’s seen problems almost no one else has, Opus is the expert, and Sonnet is a really good generalist. The effort level decides how much time any of them spends on your task.
我喜欢思考这两个设置如何相关的一种方式是:Fable 是一个见过几乎无人见过的问题的专家,Opus 是专家,Sonnet 是一个非常出色的通才。努力级别决定他们中任何一个在你的任务上花费多少时间。
Opus at low effort is like getting five minutes with an expert who has deep experience with problems like yours. They bring knowledge that isn’t anywhere in your codebase: patterns they’ve seen before, gotchas they know to check for, the kind of thing you only get from having solved a lot of similar problems. But just giving them five minutes means a quick read of your code, not a careful one.
低努力级别的 Opus 就像与一位对你的类似问题有深厚经验的专家交流五分钟。他们带来的是你代码库中任何地方都没有的知识:他们以前见过的模式、他们知道要检查的陷阱,只有从解决了很多类似问题才能获得的这种东西。但只给他们五分钟意味着快速阅读你的代码,而不是仔细阅读。
Sonnet at high effort is like giving a really good generalist the whole afternoon. They’ll read everything, run things, double-check their work, and end up understanding your specific code thoroughly. What they bring less of is that “I’ve seen exactly this before” recognition.
高努力级别的 Sonnet 就像给一个非常出色的通才整个下午。他们会阅读一切、运行各种东西,双重检查工作,最终彻底理解你的具体代码。他们较少带来的是那种”我以前见过完全相同的”的识别。
Fable, even at low effort, is that specialist glancing at the problem everyone else is stuck on and still spotting the thing no one else would. That recognition is what you’re paying the most for, so it’s worth saving for the tasks that genuinely need it.
Fable,即使在低努力级别下,就是那个瞥一眼其他人都在纠结的问题却仍然发现没人会注意到的东西的专家。那种识别是你付出最多的,所以值得为真正需要它的任务保留。
None of these is universally better. The model setting is roughly how capable; the effort setting is roughly how thorough. Most real tasks need some of both.
这些都没有普遍更好的。模型设置大致是能力水平;努力设置大致是彻底程度。大多数实际任务都需要两者的一些。
Effort, Model, and Token Consumption 努力、模型和 Token 消耗
So how do model selection, effort, and token consumption all interact? It depends on the task.
那么模型选择、努力和 token 消耗如何相互作用?这取决于任务。
On routine work at the same effort level, both models generally will get it right. The larger model consumes more tokens with extra verification steps at a higher per-token price. That’s why dropping to the smaller model for routine stretches saves real money at no quality cost.
在相同努力级别下处理常规工作,两个模型通常都能正确完成。更大的模型因额外的验证步骤消耗更多 token,每个 token 的价格更高。这就是为什么在常规工作中降级到更小的模型可以节省真钱而没有质量成本。
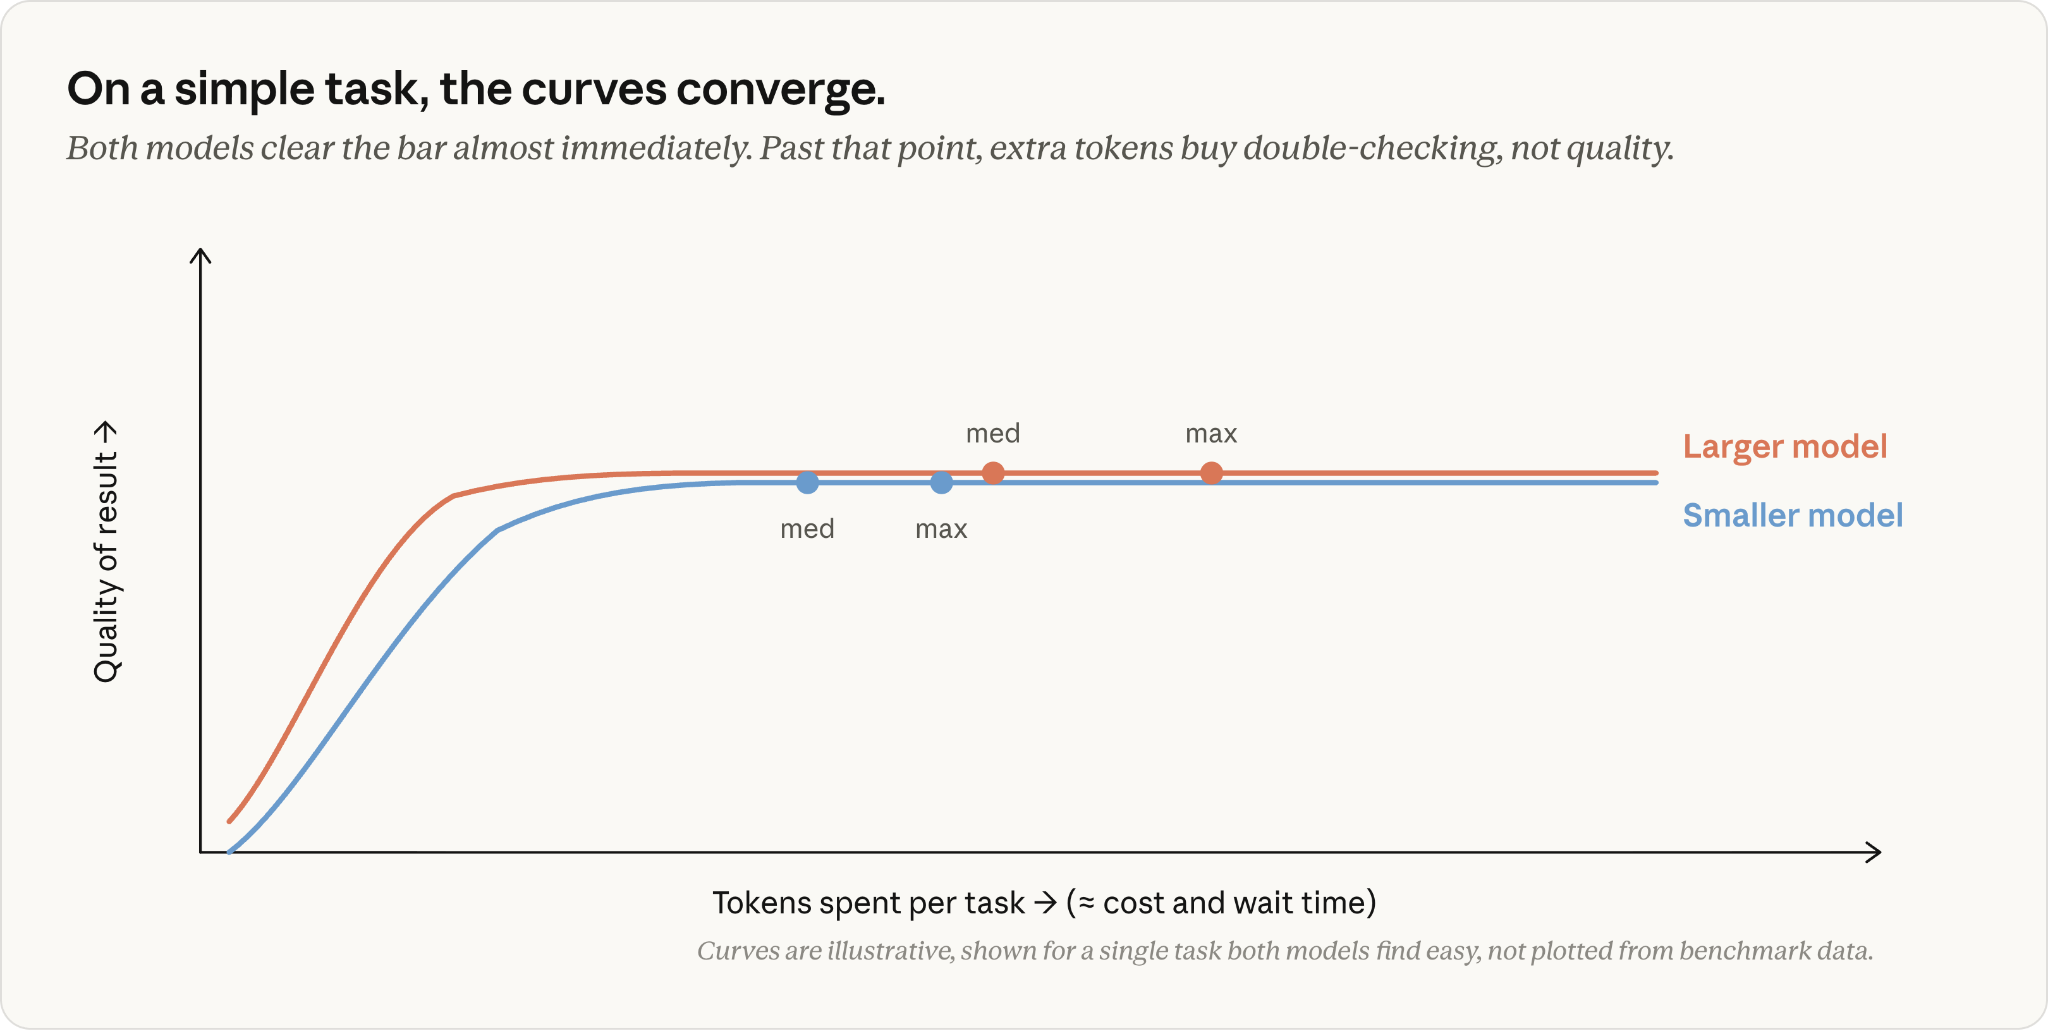
Curves are for illustration purposes only, shown for a single task simple enough to be accomplished quickly by both models. They do not represent real benchmark data.
曲线仅用于说明目的,显示的是足够简单以至于两个模型都能快速完成的单个任务。它们不代表真实的基准数据。
On harder, multi-step work, the equation is different. The smaller model has to grind toward the limit of its ability, burning iterations, while the larger model reaches the same quality bar in fewer steps.
在更难的多步骤工作上,情况不同。更小的模型必须在其能力极限边缘努力,消耗迭代次数,而更大的模型以更少的步骤达到相同的质量标准。
You’re paying more per token for the larger model, but on tasks that genuinely stretch the smaller one, the total cost per task can come out lower. Also, more importantly, the larger model can accomplish tasks the smaller one cannot even at the highest effort settings.
你为更大的模型支付更高的每个 token 价格,但在真正考验更小模型的任务上,每个任务的总成本可能更低。同样,更重要的是,更大的模型可以完成更小的模型即使在最高努力级别下也无法完成的任务。
This is most pronounced with Fable. On long, multi-step work it pulls furthest ahead. In our testing, it finished jobs Opus and Sonnet can’t reach at any effort level. It also costs the most per token, which is the other reason to save it for the work that needs it.
这在 Fable 上最为明显。在长期的多步骤工作中,它远远领先。在我们的测试中,它完成了 Opus 和 Sonnet 在任何努力级别下都无法完成的工作。它也是每个 token 价格最高的,这是另一个将它保留给需要它的工作的原因。
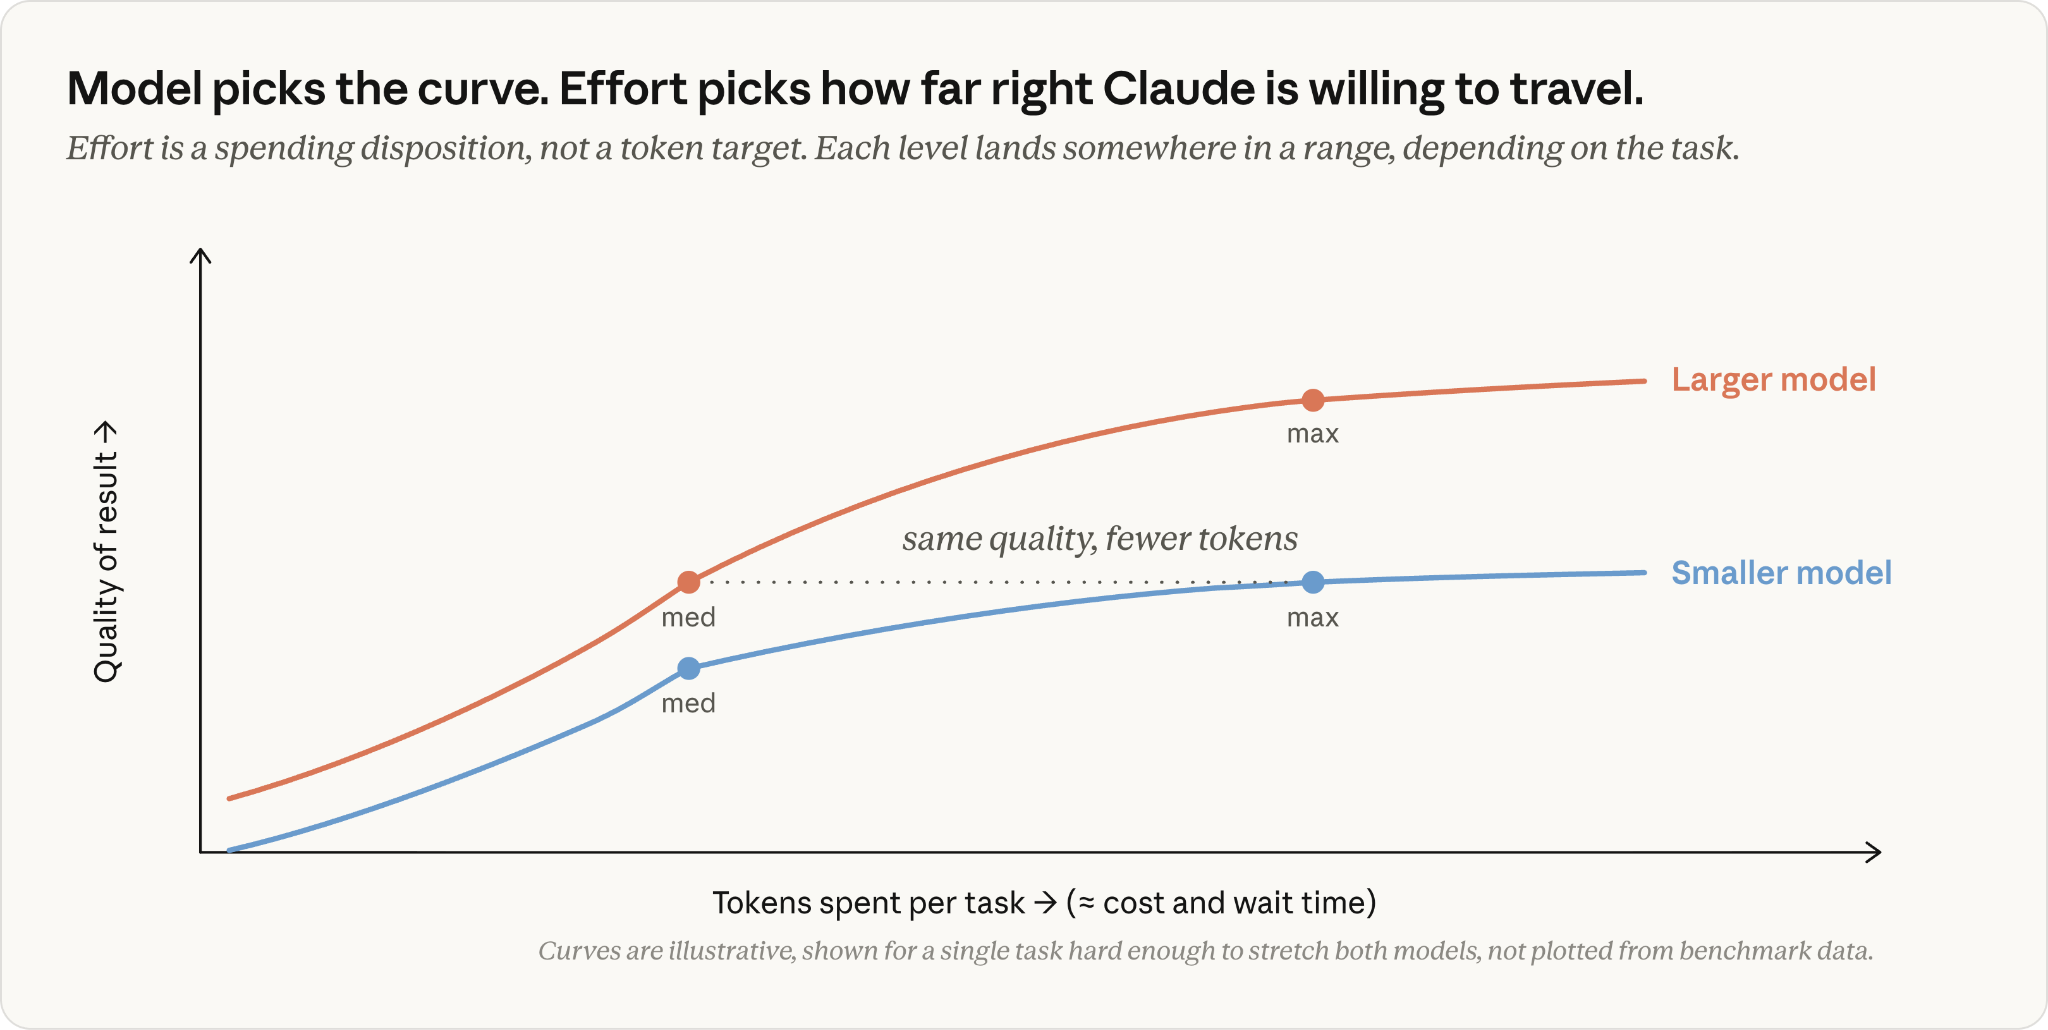
Curves are for illustration purposes only, shown for a single task hard enough to stretch both models. They do not represent real benchmark data.
曲线仅用于说明目的,显示的是足以考验两个模型的单个任务。它们不代表真实的基准数据。
The key point in the graphs above is that effort level picks how far Claude is willing to travel along the curve, but again, that doesn’t mean Claude will need to travel that far to complete the task.
上图中的关键点是努力级别选择 Claude 愿意沿着曲线走多远,但同样,这不意味着 Claude 需要走那么远才能完成任务。
Another nuance to this: effort shapes token consumption but doesn’t limit it. The only hard cap in the system is max_tokens, which truncates a response mid-stream when hit. It’s a blunt instrument, mostly relevant to API developers.
另一个细微差别:努力影响 token 消耗但不限制它。系统中唯一的硬上限是 max_tokens,它在达到时在流中截断响应。这是一个粗鲁的工具,主要与 API 开发者相关。
Softer controls, like task budgets or asking Claude to keep it brief in your prompt, are more helpful tools. They serve as guidance the model is trained to follow—it will look to conclude its tasks if it gets near the limit–rather than a wall it runs into.
更柔和的控制,如任务预算或在提示中要求 Claude 保持简短,是更有帮助的工具。它们作为模型被训练遵循的指导——如果接近限制,它会寻找结束任务的方式——而不是它撞上的墙。
Start with the Defaults, Then Reach for the Dials 从默认设置开始,然后使用调价器
Most of the time, you shouldn’t be thinking about either setting. When a result misses the mark, ask, “did Claude not know enough or did it not try hard enough?” and adjust as needed.
大多数时候,你不应该考虑这两个设置。当结果偏离目标时,问:”Claude 是不够了解还是不够努力?”然后根据需要调整。
For the full set of techniques to increase efficiency specifically, see Maximizing the value of your Claude Code sessions.
有关专门提高效率的完整技术集合,请参阅最大化你的 Claude Code 会话的价值。
最后更新: