[翻译]最大化 Claude Code 会话的价值
原文信息
- 作者: Lydia Hallie
- 日期: 2026年8月14日
- 阅读时间: 5 分钟
- 分类: Claude Code, Enterprise AI
- 产品: Claude Code
- 原文链接:Maximizing the value of your Claude Code sessions
TL;DR
- Run
/clearbetween tasks to prevent irrelevant context from accumulating - 在任务之间运行
/clear以防止不相关的上下文累积 - Set model and effort level before starting to avoid busting the prompt cache mid-conversation
- 在开始之前设置模型和努力级别 以避免在对话中途破坏提示缓存
- @-mention files instead of naming them to save Read calls
- @-mention 文件 而不是说出文件名,以节省读取调用
- Add quiet flags to noisy commands to avoid cluttered context
- 为嘈杂的命令添加安静标志 以避免上下文混乱
- Run
/contextin fresh sessions to see what’s loaded and cut unnecessary items - 在新会话中运行
/context查看加载了哪些内容并删除不必要的项目 - Run
/compactbefore long breaks while the cache is still active - 在长时间休息前运行
/compact同时保留缓存
Maximizing value 最大化价值
Until pretty recently, the tools you wrote code with were a flat fee (or free). Your editor cost the same whether you fixed one test or fifty that afternoon, so an individual task didn’t really have a price of its own.
直到最近,你编写代码的工具都是固定费用(或免费的)。无论你是下午修了一个测试还是五十个测试,你的编辑器费用都是一样的,所以单个任务本身并没有真正的价格。
With agentic coding tools like Claude Code, it does. The same completed task can also cost different amounts depending on how you use it.
但对于像 Claude Code 这样的智能编程工具来说,情况并非如此。完成相同的任务也可能因使用方式不同而产生不同的费用。
In one session, Claude reads the test and the file it covers, makes the edit, and is done in a handful of turns. In another, it greps around the repo first, reads a dozen files on its way to the same two, and every one of those turns also drags along everything else that’s been read into the conversation since this morning.
在一个会话中,Claude 读取测试及其覆盖的文件,进行编辑,几个回合就完成了。在另一个会话中,它先在仓库中搜索,读取十几个文件才到达同样的两个文件,而且每个回合都携带着自早上以来读取到对话中的所有其他内容。
It’s the same fix, but you spent a different number of tokens on it, and the whole time the model was also having to think about ten files it didn’t need.
这是相同的修复,但你花费了不同数量的 token,而且整个过程中模型还需要思考它不需要的十个文件。
Being efficient with tokens doesn’t mean using fewer of them overall. It means making sure the ones you do use go towards the thing you actually asked for.
高效使用 token 并不意味着总体上使用更少。而是确保你使用的 token 都用于你实际请求的事情上。
So let’s look at what decides the price of a token, then what decides how many of them a session sends, and along the way, what that means for how you run a session.
所以让我们看看什么决定了 token 的价格,然后是什么决定了一个会话发送多少 token,以及这对你如何运行会话意味着什么。
What decides the price of a token 什么决定了 token 的价格
You’re billed per token, but what you’re actually paying for is inference: the time it takes a GPU (or a TPU, or whatever the model happens to be running on) to run the model over your tokens.
你是按 token 计费的,但你实际支付的是推理:GPU(或 TPU,或模型运行所在的任何硬件)在你的 token 上运行模型所需的时间。
Three things decide how much of that time a token takes: which model you’re running, whether it’s an input token (going in) or an output token (coming out), and whether it was cached.
三件事决定了每个 token 花费多少时间:你运行的模型、它是输入 token(进入)还是输出 token(出去)、以及它是否被缓存。
Model 模型
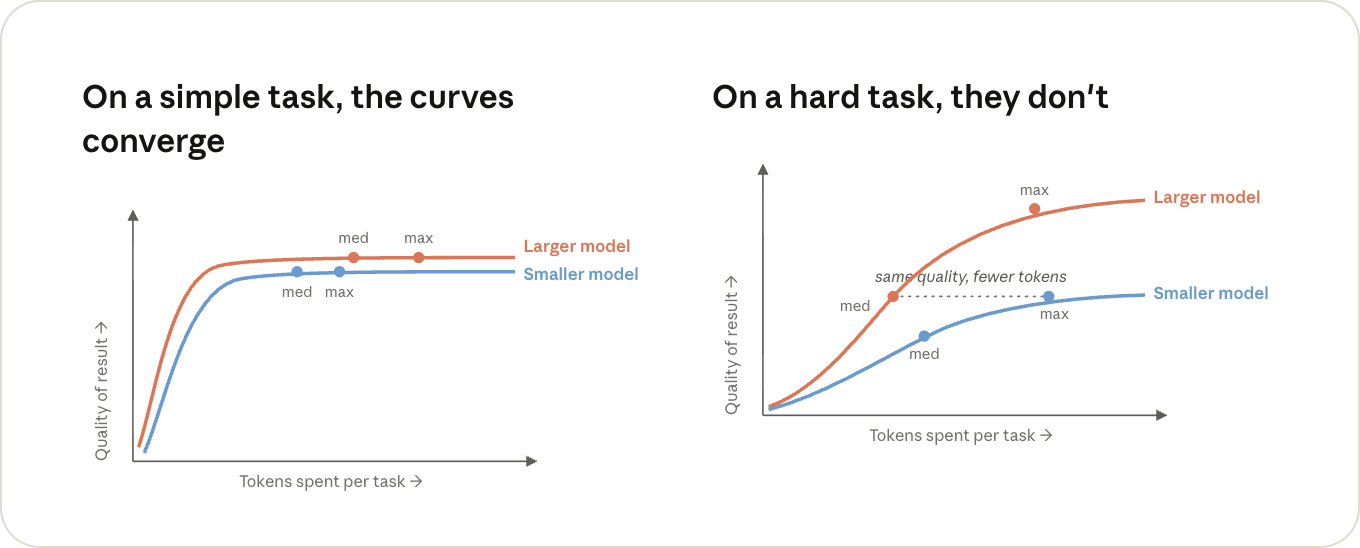
A bigger model does more work on both input and output tokens. Which model is worth it for which kind of work is a topic on its own, and we covered it in a previous post.
更大的模型在输入和输出 token 上做更多的工作。哪种模型对哪种工作值得,这是一个独立的话题,我们在前面的文章中已经讨论过。
For this post, all you need to know is that everything else we’re about to cover gets multiplied by the model’s price: use a larger model when the problem is genuinely hard or ambiguous, and a smaller one when the work is routine.
对于这篇文章,你需要知道的是,我们接下来要讨论的所有内容都会乘以模型的价格:当问题确实困难或模糊时使用更大的模型,当工作是常规的时使用更小的模型。
Input and output tokens 输入和输出 token
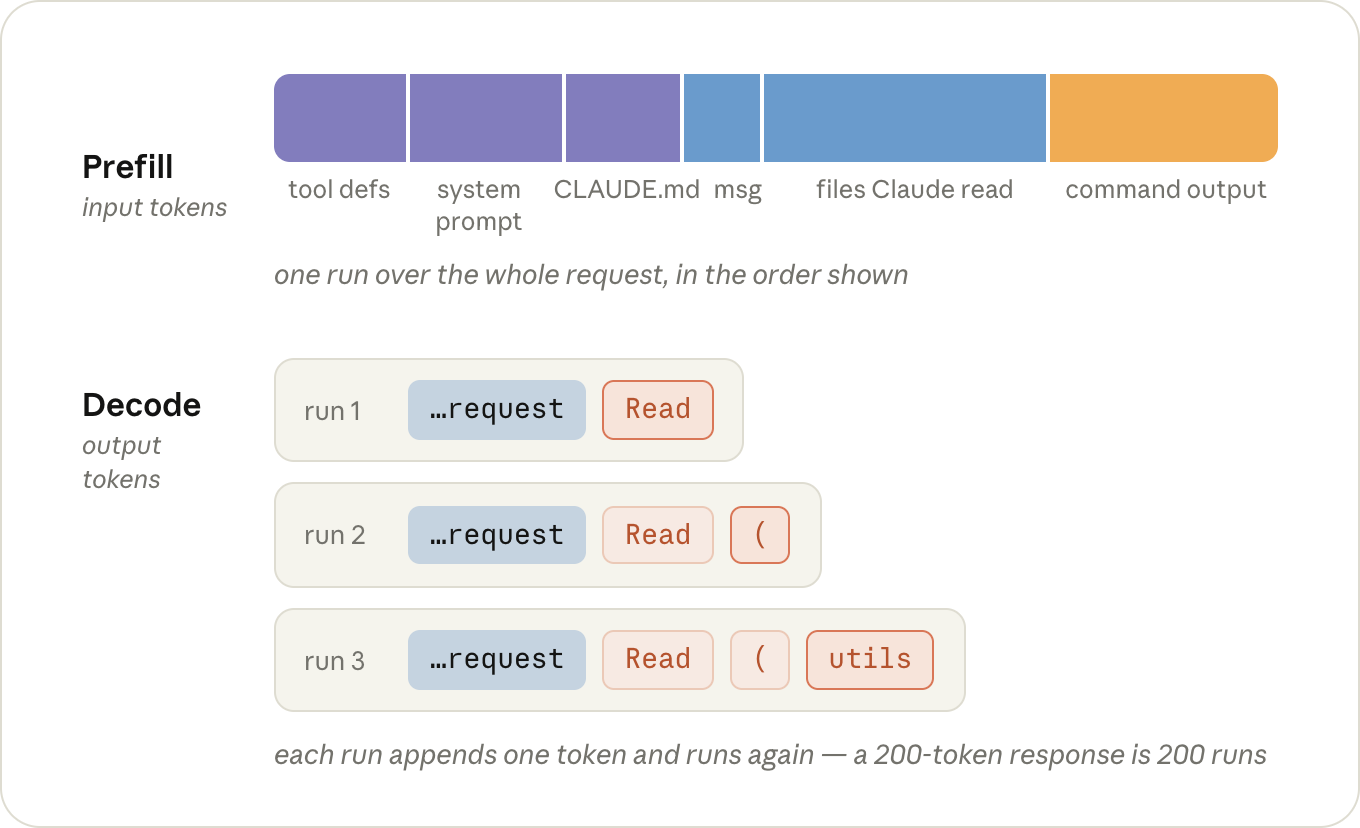
A request goes through the GPU in two phases, and they cost different amounts.
一个请求经过 GPU 两个阶段,成本不同。
First, during prefill, the model reads your request and context: the system prompt, your conversation history, and the files you attached. Those are your input tokens.
首先,在预填充期间,模型读取你的请求和上下文:系统提示、你的对话历史以及你附加的文件。这些是你的输入 token。
Then, during decode, it writes output tokens: its thinking, the tool calls it makes, and the text you see. This happens one token at a time; a 200-token response is 200 runs of the model, one after the other. Per token, decode keeps the GPU busy for a lot longer, which is why output is priced at roughly 5x input.
然后,在解码期间,它写入输出 token:它的思考、它做出的工具调用以及你看到的文本。这是一个 token 一个 token 发生的;一个 200 token 的响应是模型的 200 次运行,一次接一次。每个 token,解码让 GPU 忙碌的时间长得多,这就是为什么输出价格大约是输入的 5 倍。
A lot of the output tokens in a session are thinking tokens, and how much thinking the model does per turn is what the effort level controls. Like the model, the level you pick with /effort gets multiplied by the output price.
会话中很多输出 token 是思考 token,模型每轮做多少思考是由努力级别控制的。和模型一样,你用 /effort 选择的级别会乘以输出价格。
Prompt caching 提示缓存
If a request starts with exactly the same tokens as a request the server just saw, the state for that shared beginning comes out the same, so the server can keep it around from last time and only prefill whatever comes after it. This is called prompt caching.
如果一个请求以与服务器刚刚看到的请求完全相同的 token 开头,共享开头的状态结果相同,所以服务器可以保留上次的内容,只预填充之后的部分。这叫做提示缓存。
Reading from the cache costs 0.1x the input price, because the server loads the state instead of computing it. Writing tokens into the cache costs a bit more than normal input, up to 2x, since the server also has to hold on to the state afterwards. But the write happens once per token, and the 0.1x reads happen on every turn after it.
从缓存读取的成本是输入价格的 0.1 倍,因为服务器加载状态而不是计算它。将 token 写入缓存的成本比正常输入略高,最高 2 倍,因为服务器之后还需要保留状态。但写入每个 token 只发生一次,而 0.1 倍的读取在之后的每个回合都会发生。
Claude Code manages the prompt cache on every request, there’s nothing to turn on. However you can break it, so it’s important to know how to avoid these cost spikes.
Claude Code 在每个请求上管理提示缓存,无需开启任何东西。但你可以破坏它,所以了解如何避免这些成本飙升很重要。
An example 一个例子
Say we type “fix the failing test in src/test/auth.test.js” and send it to Claude.
假设我们输入”修复 src/test/auth.test.js 中的失败测试”并发送给 Claude。
Claude Code assembles the first request out of the system prompt (tool definitions included), your message, and the attached file. Nothing in the cache, so the whole thing goes out at full input price. The model responds with a Read call.
Claude Code 将系统提示(包含工具定义)、你的消息和附加的文件组装成第一个请求。缓存中没有内容,所以整个内容以全输入价格发出。模型以一个读取调用响应。
The model can’t fix a test it hasn’t seen, so it thinks for a moment and responds with a Read call for src/auth/login.js. Now the cache looks like:
模型无法修复它没有见过的测试,所以它思考了一会儿,然后用 src/auth/login.js 的读取调用响应。现在缓存看起来是:
- Request 1: system prompt + message + auth.test.js → full input price
- 请求 1:系统提示 + 消息 + auth.test.js → 全输入价格
- Request 2: same prefix + Read result → cache read (0.1x)
- 请求 2:相同前缀 + 读取结果 → 缓存读取 (0.1x)
Now the model wants the file under test (output). Another Read, another append, and everything goes out again: requests 1 and 2 from the cache, the second file at full price (input).
现在模型想要测试下的文件(输出)。又是一次读取,又是一次追加,所有内容再次发出:请求 1 和 2 从缓存中读取,第二个文件以全价格(输入)发出。
The model responds with an Edit (output). Claude Code applies it, appends the result, and sends everything again. Same story: the Edit and its result are new, everything in front of them is a cache read (input).
模型以一个编辑(输出)响应。Claude Code 应用它,追加结果,再次发送所有内容。同样:编辑及其结果是新的,前面的一切都是缓存读取(输入)。
The model runs the tests. Passes, in this case. Claude Code appends the test output, and out it goes again: the whole conversation so far at 0.1x.
模型运行测试。在这个例子中通过了。Claude Code 追加测试输出,再次全部发出:到目前为止的整个对话以 0.1x 发出。
The tests pass, and the model responds with a short summary (output). No tool call means nothing to append and no request 6, so we’re done.
测试通过了,模型以一个简短的总结响应(输出)。没有工具调用意味着没有东西可追加,也没有请求 6,所以我们完成了。
That’s five requests for one small fix, and every one of them contained the entire conversation up to that point. A typical turn is lopsided: tens of thousands of tokens going in, a few hundred coming out. But only what’s new in that turn gets prefilled at full price.
这是一个小修复的五个请求,每个都包含到那时为止的整个对话。一个典型的回合是倾斜的:数万个 token 进入,几百个出来。但只有那一轮中的新内容以全价格预填充。
That’s the whole per-turn bill: cache reads on the history, full input price on whatever’s new, and the output price on the response.
这就是每个回合的全部账单:历史的缓存读取、新内容的全输入价格,以及响应的输出价格。
What breaks the cache 什么会破坏缓存
The cache has to match from the very start of the request forward, and requests always go out in the same order: tool definitions, then the system prompt, then the conversation (with the newest addition at the end).
缓存必须从请求的最开始向前匹配,请求总是以相同的顺序发出:工具定义,然后是系统提示,然后是对话(最新的添加在最后)。
If anything in that prefix changes, everything behind it gets prefilled again. A tool result appended to the end of the conversation is the ideal case, since nothing is behind it. What throws the cache away is anything that changes the request further towards the front, or changes what the cache is keyed on:
如果前缀中有任何变化,后面的一切都会重新预填充。追加到对话末尾的工具结果是理想情况,因为后面什么都没有。破坏缓存的是任何使请求更靠前部分发生变化的东西,或者改变缓存键的东西:
/model: every model has its own cache/model:每个模型有自己独立的缓存/effort: the effort level is part of what the cache is keyed on/effort:努力级别是缓存键的一部分- Fast mode: also part of the key
- 快速模式:也是键的一部分
/compact: the conversation gets replaced with a shorter one/compact:对话被替换为一个更短的- Time: the cache expires after an hour on a subscription or five minutes on an API key
- 时间:缓存在订阅者一小时后或 API 密钥五分钟后过期
None of this means you should never switch models or effort. It means there are cheap moments to do it, the start of a session or right after a /compact.
这并不意味着你永远不应该切换模型或努力级别。这意味着有一些便宜的时刻可以这样做,比如会话开始时或 /compact 之后。
What decides how many tokens a session sends 什么决定一个会话发送多少 token
The main thing to know here is that nothing gets sent just once. Everything that ends up in the conversation, a file Claude read or the output of a command it ran, gets sent again on every turn after it, for the rest of the session.
这里需要知道的主要是一点:没有任何东西只发送一次。每个进入对话的内容——Claude 读取的文件或它运行的命令输出——在之后的每个回合都会再次发送,直到会话结束。
It’s cached, so each of those re-sends is cheap, but cheap isn’t nothing, and it’s taking up room in the context the model has to think around on every turn too.
它被缓存了,所以每次重新发送都便宜,但便宜不等于免费,而且它也在占用模型每个回合都必须思考的上下文空间。
That’s really the whole cost model of a session: how many tokens end up in the context, how many turns they stay there, and how many contexts you’re running at the same time.
这才是会话的完整成本模型:多少 token 进入上下文,它们在那里停留多少回合,以及你同时运行多少个上下文。
What ends up in the context 什么进入上下文
Part of what’s in the context is there before you type anything: the tool definitions, the system prompt, CLAUDE.md, and whatever else gets loaded at startup.
上下文中有些内容在你输入任何东西之前就存在:工具定义、系统提示、CLAUDE.md 以及启动时加载的任何其他内容。
Nearly everything else that gets added during the session is tool results: the files Claude reads, and the output of the commands it runs.
会话期间添加的几乎所有其他内容都是工具结果:Claude 读取的文件以及它运行的命令输出。
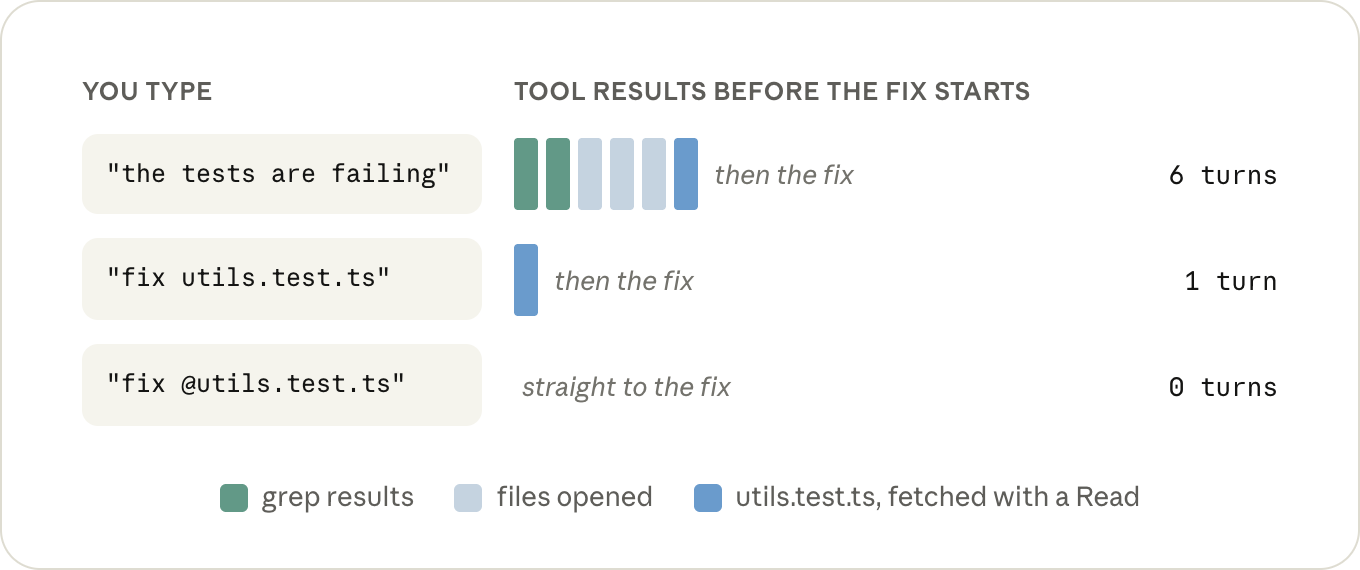
How much Claude reads mostly comes down to how much it has to figure out on its own. If you say “the tests are failing”, it first has to find out which tests: a grep or two, a few files opened to see which one is relevant, and all of those results stay in the context long after they’ve stopped being useful.
Claude 读取多少主要取决于它需要自己弄清楚多少。如果你说”测试失败了”,它首先需要找出是哪些测试:一两个 grep,几个打开的文件来查看哪个相关,所有这些结果都会在上下文中有很长的保留时间,即使它们已经不再有用。
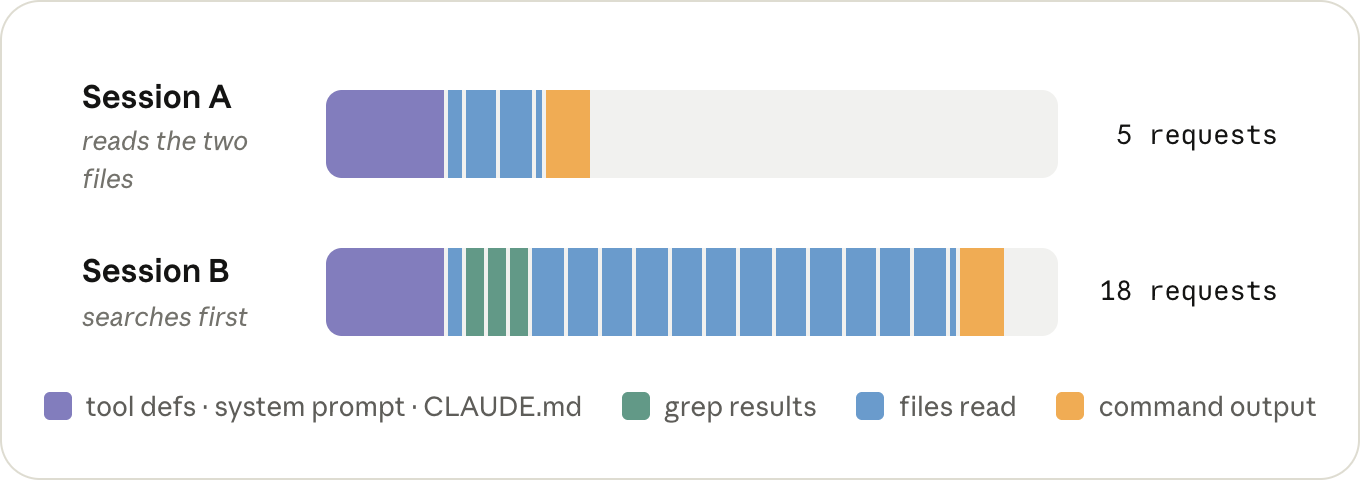
“Fix the failing test in src/test/auth.test.js” didn’t require any reading to understand. “The tests are failing” required some, and “something is broken” requires even more.
“修复 src/test/auth.test.js 中的失败测试”不需要任何读取就能理解。”测试失败了”需要一些读取,而”什么东西坏了”需要更多。
The other thing that fills up the context is the output of the commands Claude runs. Every time it runs your tests, a build, or a git log, whatever that prints gets appended to the conversation just like a file it read, and stays there for the same number of turns.
另一个填满上下文的东西是 Claude 运行命令的输出。每次它运行你的测试、构建或 git log,无论打印什么都会被追加到对话中,就像它读取的文件一样,并且在相同数量的回合中保留。
Really big outputs are actually fine: after 30,000 characters Claude Code writes the output to a file and only puts a short preview and the path in the conversation (and you can configure the threshold with /output-lines).
非常大的输出实际上没问题:超过 30,000 个字符后,Claude Code 会将输出写入文件,只在对话中放置一个简短的预览和路径(你也可以用 /output-lines 配置这个阈值)。
The problem is everything under that. A test runner that prints 400 passing tests one line at a time comes in under the limit, and those 400 lines are now part of every remaining turn.
问题是在这个阈值以下的任何东西。一个一次打印 400 个通过测试的测试运行器低于这个限制,但这 400 行现在成为了每个剩余回合的一部分。
Claude will often take care of this for you with flags and tail, and if you’d rather not leave it up to Claude, there’s a small hook in the docs that rewrites noisy commands before they run so only the lines that matter come back.
Claude 通常会用 flags 和 tail 为你处理这个问题,如果你不想交给 Claude,文档中有一个小 hook 可以重写嘈杂的命令,只返回重要的行。
How many turns it stays there 它在那里停留多少回合
One long session costs more than the same work spread over a few short ones, and by more than you’d think, because turn 40 is also re-reading the 39 turns before it. You want the context in your session to be short and relevant, so don’t carry one task’s context into the next: /clear when you start something new, and /compact when the earlier part of the same task is done.
一个长会话比将相同的工作分散到几个短会话中花费更多,而且比你想象的更多,因为第 40 回合也在重读之前的 39 个回合。你希望会话中的上下文简短且相关,所以不要将一个任务的上下文带入下一个:在开始新任务时用 /clear,在同一任务的前面部分完成后用 /compact。
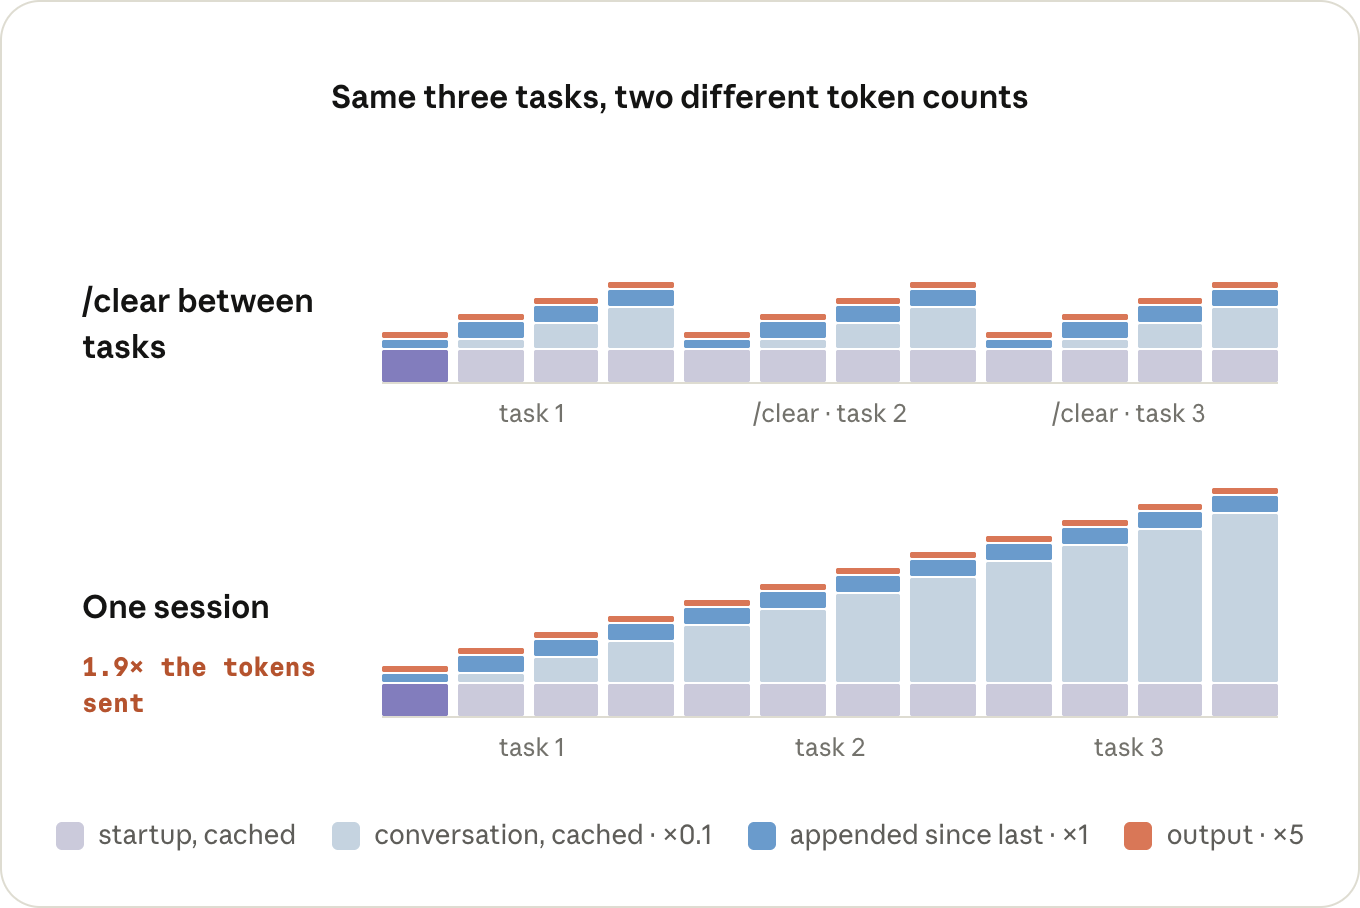
Keep an eye on turns that happen when you’re not typing, too. A /review command might run for a few minutes and read a dozen files, and unless you run /compact before you pick up the next task, those files stay in your context.
也要注意在你没有输入时发生的回合。/review 命令可能运行几分钟并读取十几个文件,除非你在开始下一个任务之前运行 /compact,否则这些文件会留在你的上下文中。
Subagents 子代理
The other way to keep something out of your context is to have it happen in a different one, which is what subagents are for. A subagent gets its own context window, with its own system prompt, the tools, and your CLAUDE.md, but not your conversation. It runs its own turns, and the only thing that comes back to the main session is its answer.
另一个让东西远离你上下文的方法是让它在不同的上下文中发生,这就是子代理的用途。子代理获得自己的上下文窗口,有自己的系统提示、工具和你的 CLAUDE.md,但没有你的对话。它运行自己的回合,唯一回到主会话的是它的答案。
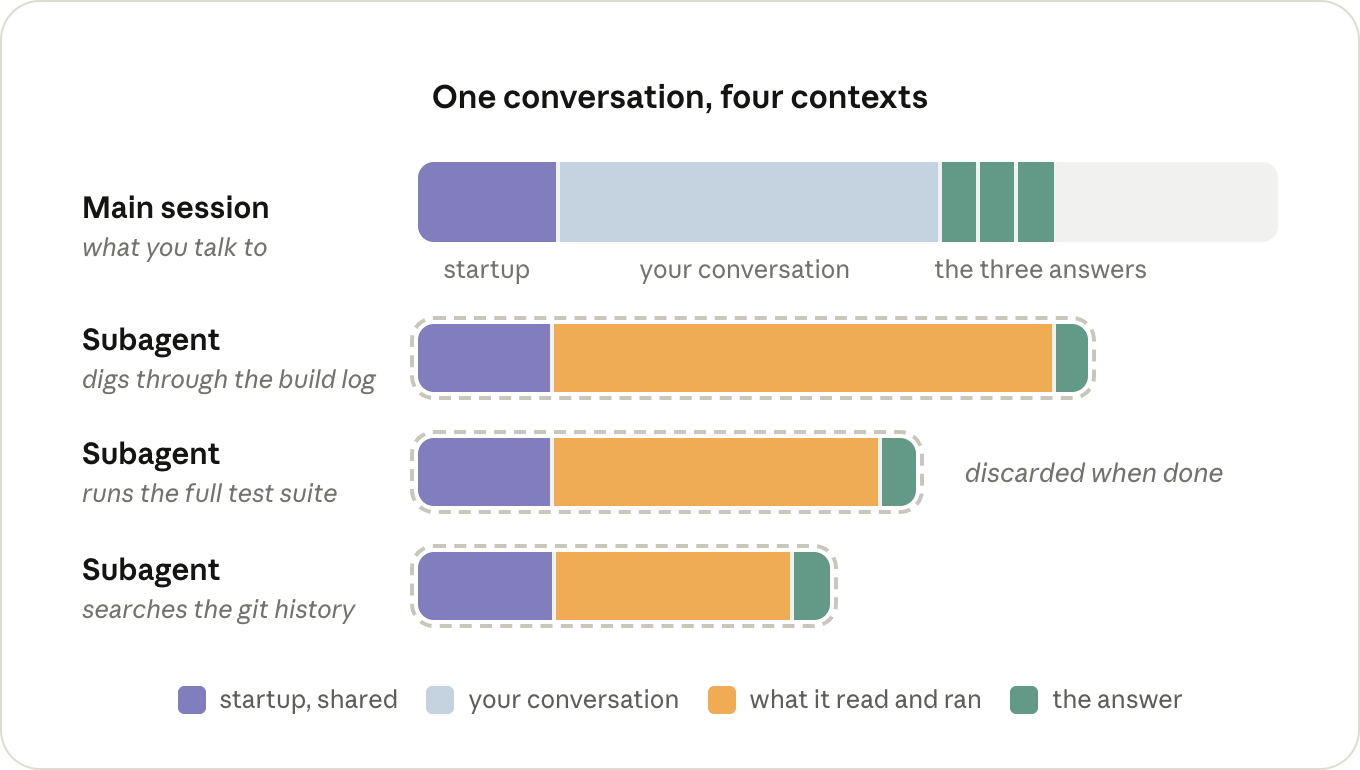
The downside of not having your conversation is that a subagent sometimes has to re-read things the main session already had, and it’s paying for its own turns while it does. For a small job it’s just overhead.
没有你的对话的缺点是子代理有时需要重新读取主会话已经有的东西,而且它在这样做时支付自己的回合费用。对于小任务来说这只是开销。
It pays off when a job produces a lot of output you don’t need to keep, like going through a log. Claude will often reach for one on its own for that kind of thing, and you can ask for one directly when it doesn’t (“go through this log in a subagent”). Just keep in mind that the main session only gets back what the subagent chose to report.
当一项工作产生大量你不需要保留的输出时,比如遍历日志,这就值得了。Claude 通常会自己为此使用一个,你也可以在它没有主动使用时直接要求它(”在一个子代理中遍历这个日志”)。只要记住主会话只能取回子代理选择报告的内容。
Where to look first 首先关注什么
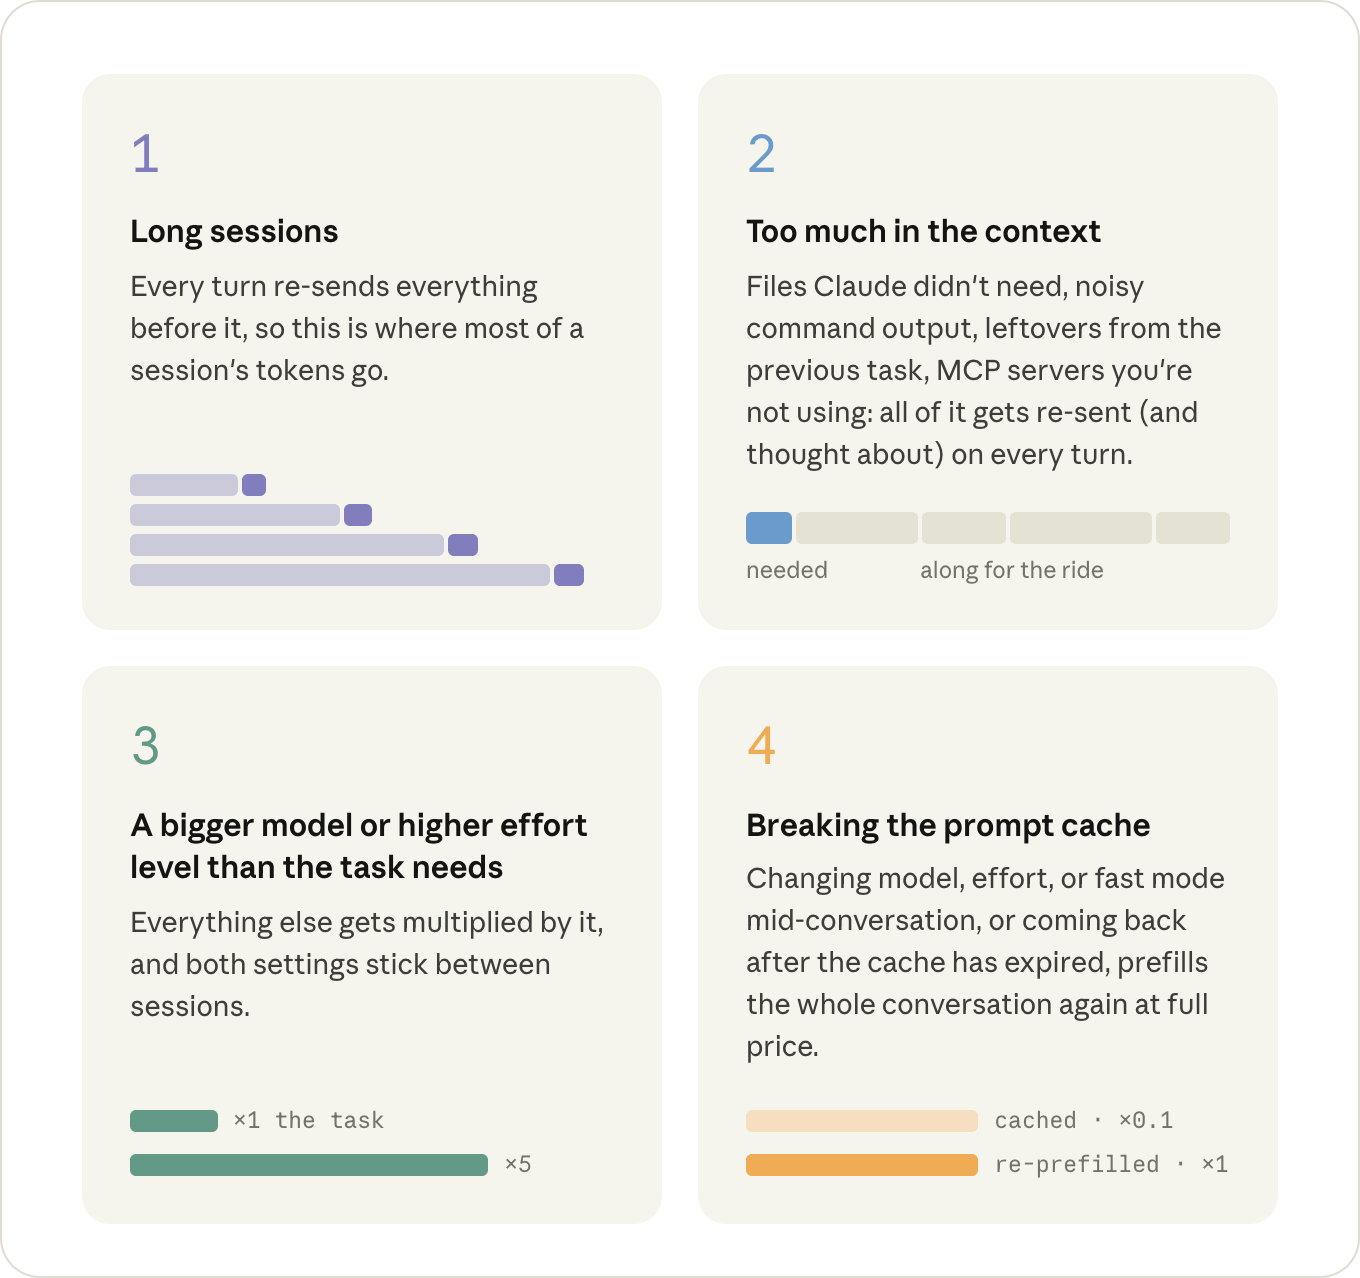
Of everything above, four things are worth keeping an eye on, roughly in order of how much they cost:
在上述所有内容中,有四件事值得关注,大致按成本排序:
- Model selection 模型选择
- Effort level 努力级别
- Context size 上下文大小
- Session length 会话长度
Additional Tips 额外技巧
File Referencing 文件引用
@-mention files instead of naming them. The file gets attached to your message directly, which saves a Read call.
@-mention 文件而不是说出文件名。文件直接附加到你的消息上,这节省了一次读取调用。
最后更新: